LLM Battle 7 - Muse vs Qwen Rematch!
Muse Glimmer is rematched against Qwen 3.8 27B using TalkWithMe, with Qwen’s reasoning level increased to high for comparison.
Videos
Find videos about LLM models, hardware, runtimes, benchmarks and practical AI workflows.
Muse Glimmer is rematched against Qwen 3.8 27B using TalkWithMe, with Qwen’s reasoning level increased to high for comparison.
Tests Inworld Realtime TTS-2 and TTS-2 Flash for voice quality, cloning, steering, multilingual support, and API integration against ElevenLabs.
Tests Qwen3.8-Max-0902, described as an upgraded snapshot of qwen3.8-max.
Evaluates OLMo using traces, tokens versus wall clock comparisons, souping methods, and performance metrics on a private H100 cluster.
Evaluates Claude Fable 5.1 via BridgeBench, Claude Code in BridgeMind One, and comparisons against Fable 5, Opus 5, GPT 5.6 SOL, Grok 4.6, and Kimi K3.
Evaluates Claude Fable 5.1 via browser OS tests, C++ skate and rally games, 3D CAD models, frontend design, watch websites, and an UltraCode Subway FPS test.
Introduces and tests Fable 5.1 and Mythos 5.1.
Demonstrates building short term memory with MessageHistory, MemorySaver, trim_messages, and SummarizationMiddleware, plus long term memory via InMemoryStore and SQLite in LangChain.
Eleven universal tips for improving coding agent reliability cover instruction hygiene, context management, avoiding escalation, and systematic validation based on cited studies.
Tests FreeToken against llama-server baseline using OpenCode on 12GB VRAM to evaluate performance constraints.
Tests MTPLX v2.10.0 optimizations for local Qwen3.8-Flash-Next coding agents via .NET migration and SVG image generation comparisons against oMLX.
Compares Grok Bot and Hermes Agent setups, capabilities, and reliability for automated workflows and local action execution.
Locally installs and tests JetSpec's speculative decoding to demonstrate real speedup numbers for large language model inference.
Tests Tencent HY4 Preview on coding, 3D game dev, and agentic tasks, comparing it against Qwen 3.8, GLM 5.3, DeepSeek V4 Flash Vision, Kimi K3, Claude Opus 5, and GPT-5.6 using WOAI Bench.
Benchmark compares Qwen 3.5 9B, Ornith 1.5 9B, Defiant Fable, Heretic Qwen, and Hauhau Qwen on 12GB GPUs like 3060, 4070, or 1080 Ti.
Locally installed and tested open-weight text-to-speech model Breeze TTS 2, designed for real-time interaction.
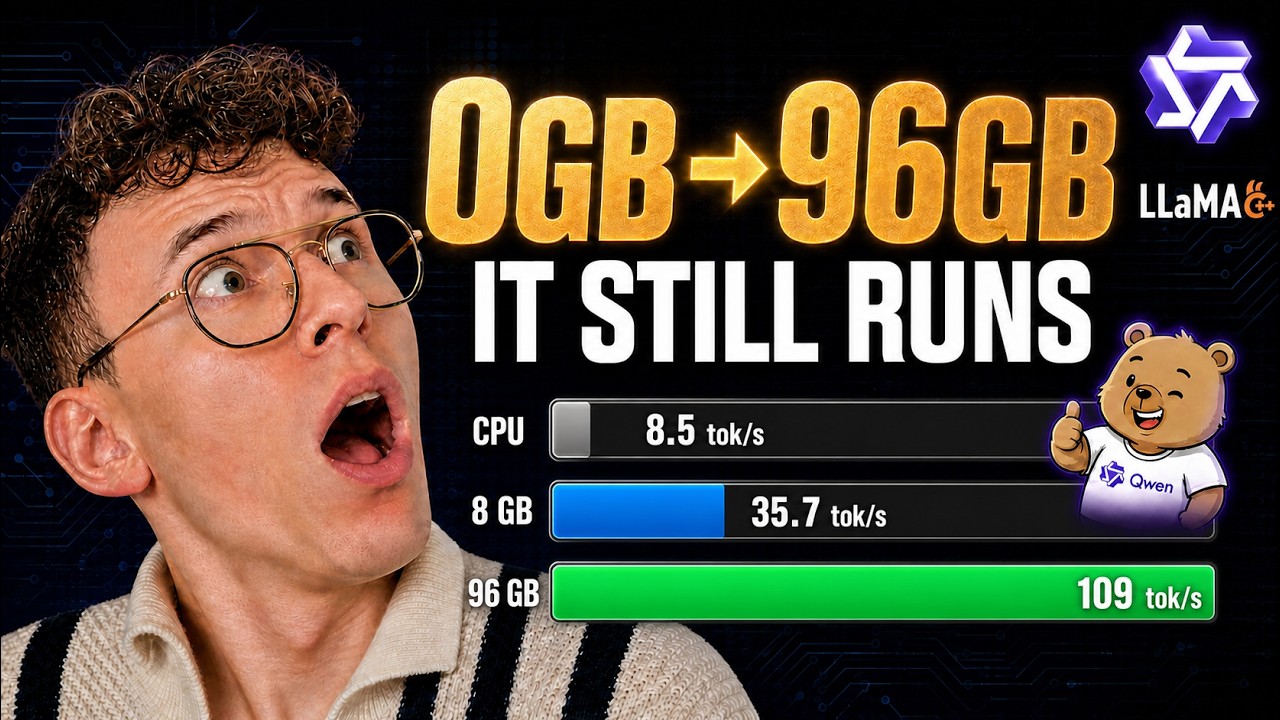
Benchmarked Qwen3.8-Flash-Next in llama.cpp across 0–96GB VRAM using AMD Ryzen 9 9950X and NVIDIA RTX PRO 6000 Blackwell, measuring decode speeds, prefill gains, and configuration impacts.
Tests Tencent HY4 preview on browser workflows, C++ game creation, FPS development, frontend design, Blender scene generation, and a wrestling game.
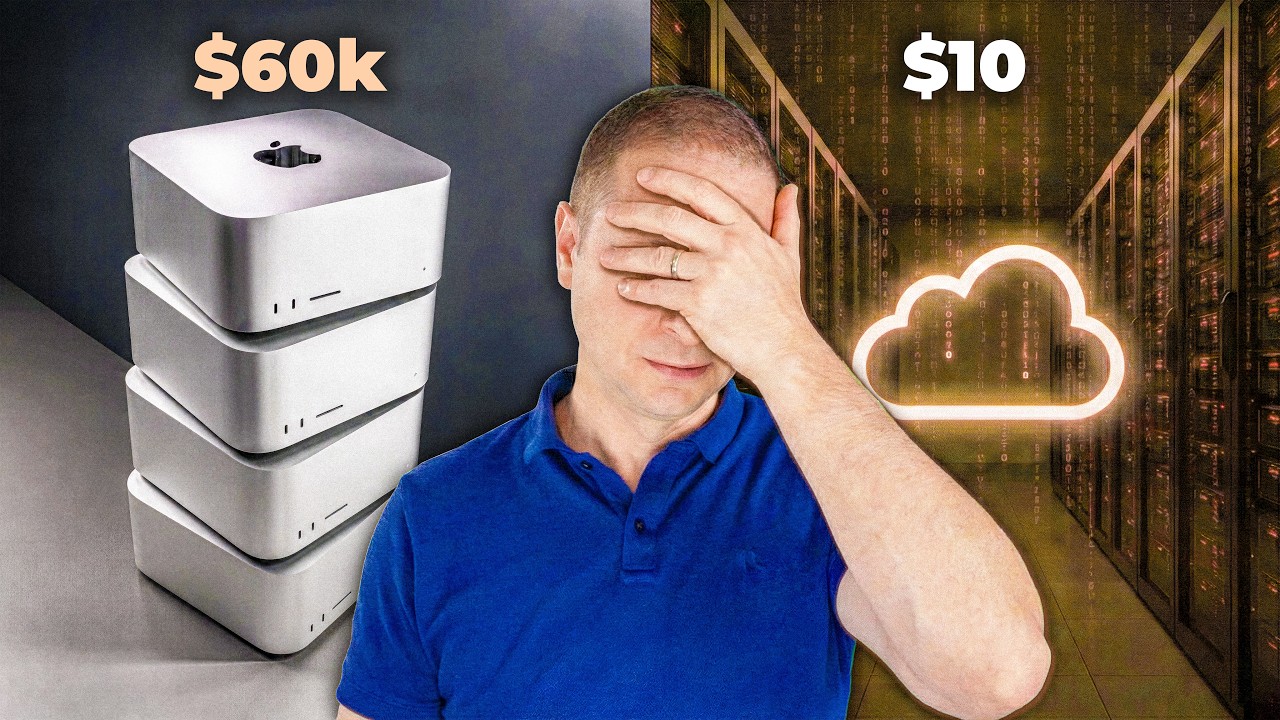
Compares a $60,000 512GB Mac Studio cluster running Kimi K3 against a $10/month cloud coding agent to evaluate performance differences.
Demonstrates setting up DeepSeek Harness with local Qwen 3.8 27B via Ollama to autonomously build and deploy a portfolio site to Vercel using GPU-generated tokens.
Compares the Pi coding harness against OpenCode through testing network proxies, system prompts, roles, subagents, compaction, and integration with Agent Voice.
Demonstrates SureThing.io, a browser-based platform enabling zero-infrastructure AI agents that handle messaging, research, and deliverables via simple texting.
Evaluates Zhipu GLM-5.3 using Inferencer App on Mac Studio M3 Ultra 512 GiB with GLM-5.3-MLX-Q4-INF, testing thinking modes, coding stress tests and logic against cloud performance.
Tests Dirk Qwen 3.8 27B GGUF from peculiar-ragdoll using Performance, Memory, Agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot benchmarks.
Builds Pydantic models with with_structured_output using Nemotron 3.5 Lightning on OpenRouter to generate consistent JSON fields for sentiment analysis and ticket routing via LangChain.
Locally installs and tests Thomson-1.0-Small, a model designed for high-stakes professional work across legal, tax, and journalism domains.
An AI coding agent uses Cursor, Node.js 24, TypeScript and Zapier TypeScript SDK to move a Google Calendar event and DM attendees via Slack.
Demonstrates setting up Pithagoras, an open-source local AI agent with native browser control, using four onboarding components: identity, intake, action access, and escalation path.
Locally installs and tests Pipecat's PhoneLLM Alpha 1, an open-weights model for voice agent use cases.
Compares DeepSeek V4 Flash and Qwen 3.8 Flash Next using Unsloth UD-IQ1_S 1-bit builds on 19 hard problems via CPU-only and RTX 5090 expert layer offload benchmarks.
Hands-on guide to training kyutai pockettts models from scratch for custom languages and voices using local resources.
Covers GLM 5.3 Flash, Qwen 3.8 Flash Next, Minimax FastH3, Hy4, Ox Alpha, Gemini 3.5 Transcribe, Omni 1.1 Flash, Block 3D, FixAnything, and World Humanoid Games.
Benchmark IBM Granite 4.2, Qwen 3.8 27B, Gemma 4, and Ornith 1.5 on an RTX 5090, measuring KV cache cost, usable context, generation speed, coding, math, and tool calling via Python tests.
Hands-on comparison of GLM-5.3-Flash vs Qwen3.8-Flash evaluating bug fixing, vision coding capabilities, and AI flirting performance through three distinct tests.
Demonstrates LCEL and the pipe operator to build sequential and parallel chains using StrOutputParser, .batch(), .stream(), and model fallbacks, verified via LangSmith.
Runs GLM-5-Flash using Inferencer App v2.3.5 on an M3 Ultra 512 GiB system with the inferencerlabs/GLM-5.3-Flash-MLX-Q9 quantization via local testing.
Tests Hy4 preview, a new-generation Mixture-of-Experts (MoE) flagship model developed by the Tencent Hy Team.
Runs Qwen3.8 27B locally using Superlinked Inference Engine (SIE) for efficient execution.
Compares MLX/oMLX and GGUF with llama.cpp for local inference of Qwen3.8-Flash-Next 125B on Apple M5 Max, achieving ~60 tokens/sec with oMLX 0.6.3 and Lightning MTP.
Tests Qwen 3.8 27B Ridge from Empero AI on 16GB GPUs using benchmarks including OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot.
Benchmarking Ornith 1.5 9B and 35B, Qwen 3.8 27B, and Gemma 4 on an RTX 5090 using llama-server with 4-bit weights and FP16 KV cache via code-graded metrics.
Tests Qwen 3.8-Flash-Next 1-bit to 4-bit IQ4_XS via llama.cpp on GMKtec EVO-X2 against Qwen 3.8-27B references using four one-shot tests, reporting ~20 tok/s and peak memory usage.
Step-by-step guide to running unsloth/GLM-5.3-Flash-GGUF locally using CPU and RAM.
Tests GLM5.3 Flash performance on browser workflows, game generation, C++ coding, model training, and Blender & Godot Street Yeet tasks.
Benchmarks Qwen 3.8 Flash Next on Intel Core Ultra 9 285K CPU versus RTX 5090 offloading using llama.cpp, measuring throughput and perplexity for 1-bit and 2-bit quantizations.
Compares Superlinked Inference Engine (SIE) with vLLM.
Evaluates Qwen3.8-Flash-Next-MLX-Q9 and Q4 variants using Inferencer App v2.3.4 on an M3 Ultra 512 GiB system via local testing.
Weight-level teardown shows 131 of 866 tensors changed in Qwen 3.8 27B Uncensored via abliteration, tested on RTX 5090 with llama-server against a 30-prompt refusal benchmark.
Tests Qwen3.8-Flash-Next coding and Splunk Cyber CTF performance, investigates hallucinations caused by Qwen Sparse Attention, and demonstrates fixing issues via sparse attention settings.
Reviews Qwen 3.8-Flash-Next specs and Unsloth GGUF sizes.