Build A Custom Browser Extension [SUPER Easy!]
Demonstrates building a Chrome extension using the GLM 5.2 model, detailing installation via Developer Mode and loading unpacked files.
Videos
Find videos about LLM models, hardware, runtimes, benchmarks and practical AI workflows.
Demonstrates building a Chrome extension using the GLM 5.2 model, detailing installation via Developer Mode and loading unpacked files.
Qwen 3.6 and Gemma 4 variants are tested to design and build a full-screen visualizer using MusicPlayer, with results hosted in the ext-mp-ai-visualizers repo.
Demonstrates Manus AI Agent building native Windows apps, mobile app remote demos, build automation, troubleshooting, marketing video creation, and icon generation.
Compares Intern Science Agents A1 35B MoE against Qwen 3.6 35B A3B via Performance, Memory, Agency, OpenAI Human Eval, Sand Physics and Dungeon Crawler tests on a 16GB local setup.
Explains FTPO and local testing for Qwythos-9B-v2, which retains deep chain-of-thought reasoning while fixing the looping bug found in the base Qwythos model.
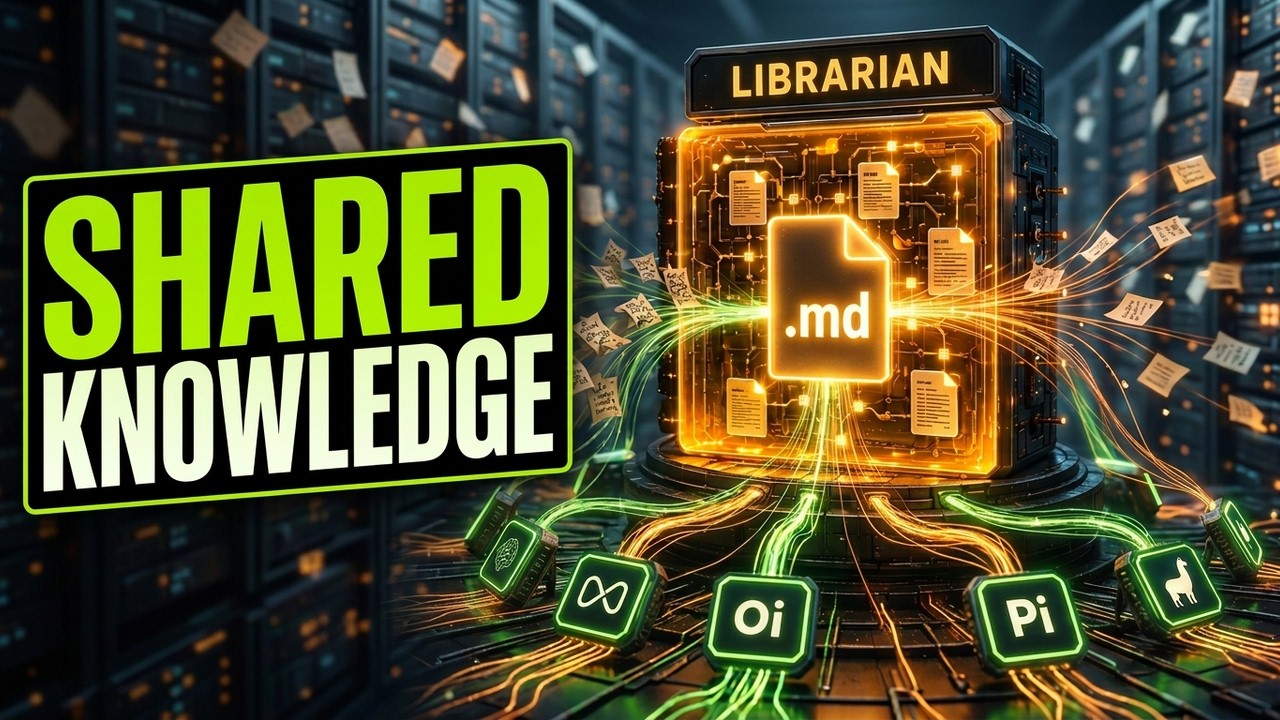
Demonstrates understory, a local memory layer using markdown files, OKF spec, and MCP protocol with a librarian agent running on llama.cpp for shared knowledge across multiple AI setups.
Claude Fable 5 and GPT-5.6 Sol are evaluated using a single complex prompt requiring generation of a rotating döner kebab with real fire physics and fluid dynamics.
Claude Code and Archon generate a batch of finished, human-approved video ads from a product catalog using Higgsfield.
MOSS-Transcribe-Diarize 0.9B performs end-to-end long-form multi-speaker transcription, diarization, timestamp generation, and acoustic event awareness.
Covers updates on GPT 5.6, Grok 4.5, Seedream 5 Pro, Muse Spark 1.1, LingBot World 2, GPT Live, ABot World, ProxyPose, SeFi image, PixWorld, Wan Streamer 0.2, Mira, Humanoid surgery, Booster T2, Alaya
Locally installs and tests SIE, an open-source inference engine serving embeddings, reranking, and entity extraction.
Tests Meta Muse Spark 1.1 via castle scene generation, browser workflows, C++ games, frontend design, multimodal coding, 3D modeling, creative writing, timelines, and FPS games.
Locally installs and tests Tess-4-27B with an EAGLE-3 speculative-decoding draft head using migtissera/Tess-4-27B-EAGLE3.
Demonstrates parsing invoices and contracts with Upstage Studio integrated via MCP server into Claude Code to extract structured data such as dates, totals, and vendors into an Excel sheet.
Demonstrates building coding agents in OpenCode using a network proxy, creating Ranger 1 and GrizzledSeniorDev agents, and augmenting them with skills through examples.
Benchmarked a local AI model hidden inside macOS 27 on a $10,000 Mac Studio to evaluate its performance speed.
Covers updates on GPT-5.6, ChatGPT Ambitious Work, GPT-Live, SolBonk Game, Grok 4.5, Muse Spark 1.1, Muse Image, Claude Fable 5, Cowork, Reflect, Global Workspace, Google Photos Video Remix and Seedre
Demonstrates building a support agent using Pydantic AI 2.0 capabilities, which bundle instructions, tools, and settings, showing reusability across different agents without code changes.
Locally installed lift extracts structured JSON from PDFs and images across 10 languages using schema-based processing.
Benchmarks GPT-5.6 Sol, Terra, and Luna against Claude Fable 5, Grok 4.5, and GLM 5.2 via Artificial Analysis, OSWorld, Terminal-Bench, coding, frontend generation, and cost evaluations.
Reviews GPT 5.6 against Claude Fable via demos of realtime anime, liquid simulation, music, 3D modeling, math, cancer ID, deep research and financial presentations.
Tests GPT-5.6 via browser workflows, Apple Vision Pro apps, hardware drivers, city timelines, skydiving simulations, Subway FPS games, and frontend websites.
Muse Spark 1.1 is introduced as a strong agentic and coding model offered at a very low price.
Evaluates GPT 5.6 via BridgeBench, Codex, GPT 5.6 SOL, and multi-agent orchestration in BridgeSpace against Claude Fable 5 and Grok 4.5 using identical workflows and real production tasks.
Installs and tests Pegaflow, a production-grade external KV cache service that plugs into vLLM.
Tests Tencent's 295B MoE Hy3 locally and in the cloud, comparing it against GLM 5.2 and Gemini 3.1 Pro to evaluate its performance levels.
Demonstrates configuring OpenCode with a local LLM provider, then testing it via a bug hunt and implementing a feature in a Java MCP library verified with MCP Inspector.
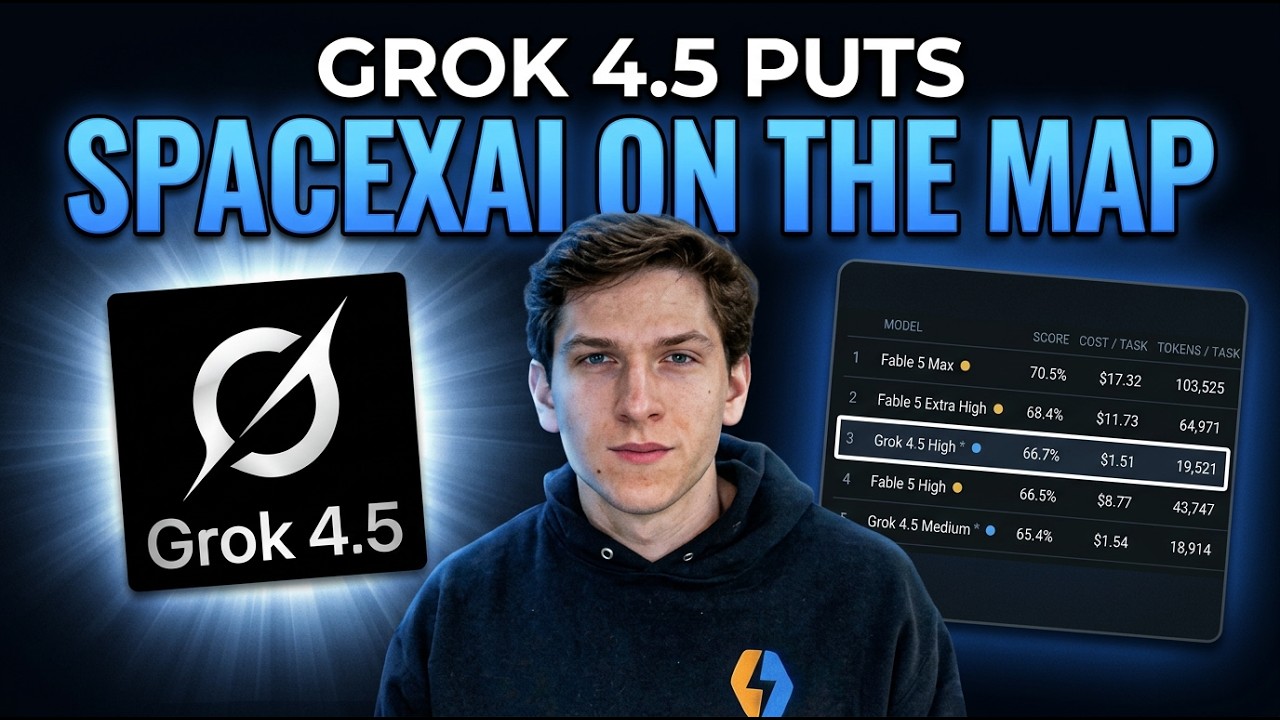
Evaluates Grok 4.5 via Artificial Analysis coding index, building apps, and comparing against Fable 5 and GPT 5.5, noting CursorBench leakage.
Compares Qwythos 9B v3 MTP and Qwen 3.5 9B MTP via Performance, Memory, Agency, OpenAI Human Eval, Expense Tracker, and Memory Match Game tests on an 8GB VRAM GPU.
Locally installs and tests Nemotron-Labs-3-Puzzle-75B-A9B, a deployment-optimized model produced using Iterative Puzzle.
Tests Grok 4.5 via Terminal Bench, SWE Bench Pro, and real-world coding tasks, comparing performance, pricing, speed, and token efficiency against Claude Fable 5, GPT-5.5, Claude Opus 4.8, and Gemini
Tests Grok 4.5 against GPT and Claude Opus via browser OS, skydiving simulation, sprite sheet games, Linux drivers, frontend design, C++ skate games, 3D modeling, and Subway FPS tasks.
Evaluates local AI inference speed using Llama.cpp with Gemma 4 and GPT-OSS models, plus OpenClaw agents, on Asustor Lockerstor 4 equipped with 2x10GBe and AMD Ryzen CPU.
Demonstrates scaling AI agent memory using Redis Iris Context Retriever and Agent Memory, replacing Markdown wikis for multi-user production systems with real-time data handling and access control.
Demonstrates using Runway, Seed Dance 2.0, Gemini, Veo 3.1, Remotion, and Codex for intros, transitions, backgrounds, B-roll, logos, lower thirds, infographics, and animated talking heads.
Evaluates Grok 4.5 via BridgeBench agentic coding workflows, comparing performance against Claude Opus 4.7, GPT 5.5, and Fable 5 using live leaderboard scores.
Locally installs and tests ThinkingCap: Qwen 3.6 27B, evaluating its capability with 50% less thinking tokens.
Demonstrates selecting optimal context window sizes for local LLMs by measuring VRAM usage and testing processing capabilities with English text and Java code inputs.
Locally installs Nemotron-Labs-Audex-2B, a unified audio-text LLM developed by NVIDIA.
Locally tests Sakana Fugu, described as a multi-agent system functioning as a single model.
Demonstrates cloning, initial build, verification and testing of llama.cpp, plus explains quantization, picking model sizes, exceeding VRAM and testing an MoE model.
Benchmarking DFlash speculative decoding with Qwen 3.6 27B via llama.cpp on RTX PRO 6000 Blackwell using aiperf and MATH-500, measuring throughput gains and accuracy against baselines.
Demonstrates using openart_ai Director to generate up to 5 minutes of continuous video via chat, maintaining consistency in characters, voices, and story throughout the production process.
Demonstrates building a local deep research agent with Qwen models, implementing sub-agent delegation and tool quotas on AMD Ryzen AI Max Series and Radeon AI PRO R9700 GPUs.
Demonstrates configuring local LLMs like Qwen3.6 MTP and Gemma 4 with GitHub Copilot, Codex, and Claude Code on LM Studio or Ollama, plus setting system prompts in LM Studio to prevent looping.
Tests Tencent Hy3 295B MoE on 2x RTX PRO 6000 Blackwell GPUs using MXFP4 quantization via vLLM and SGLang for coding, agents, and real-world speed.
HY3 undergoes frontend coding, Three.js, HTML5 Canvas, and agentic programming tests, comparing code quality, speed, efficiency, reasoning, and visual output against Fable 5, Claude Opus 4.8, Claude S
Tests Hy3, a 295B MoE with 21B active parameters and 3.8B MTP layer parameters.
A homebrew setup uses old hardware and LMStudio to host a local AI code assistant, testing large, dense, and MoE models while comparing their performance.
Tests Tencent HY3 against GLM and DeepSeek via browser OS, C++ skate game, Linux driver, skydiving, city timeline, frontend design, 3D model, and subway FPS evaluations.