Ternary Bonsai 27B benchmarked and tested vs Qwen 27B - 16GB Local LLM setup
Evaluates Ternary Bonsai 27B against Qwen using Performance, Memory, Agency, OpenAI Human Eval, Dungeon Crawler, Blender, and Sand Physics tests on a 16GB local system.
Videos
Find videos about LLM models, hardware, runtimes, benchmarks and practical AI workflows.
Evaluates Ternary Bonsai 27B against Qwen using Performance, Memory, Agency, OpenAI Human Eval, Dungeon Crawler, Blender, and Sand Physics tests on a 16GB local system.
Compares Kimi K3 with Qwen3.8 across two tasks.
Tests Qwen 3.8 Max Preview via woaibench.ai on frontend dev, SVG gen, 3D games, UI design, reasoning, and multimodal tasks, comparing results against Kimi K3 and GPT-5.6 Sol.
A multiplayer 3D minesweeper game with ELO, matchmaking, and networking is created using a one-shot prompt via Qwen 3.8 Max Preview on Qwen Cloud.
Tests Bonsai 27B binary and ternary variants against Qwen 3.6 35B-A3B and Gemma 4 12B on an RTX 3060 using llama.cpp, measuring generation speed, total memory footprint, and performance on web design
Evaluates Osaurus, a local, free coding tool featuring a beautiful UI and mascot, to determine its quality.
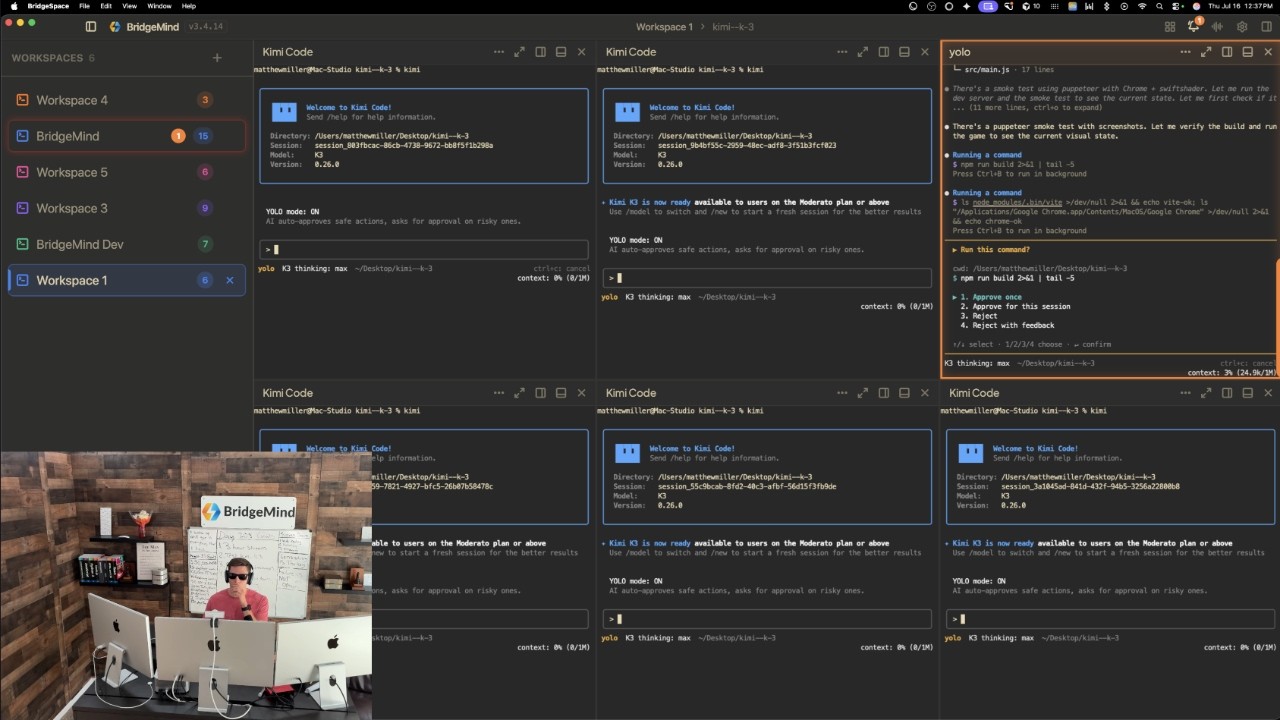
Evaluates Kimi K3, Grok 4.5, Fable 5, and GPT 5.6 via identical prompts in BridgeSpace across front-end therapy dashboard, full-stack AI therapist app, and Angry Birds game tests.
Evaluates Tenstorrent AI cards, which are not GPUs, highlighting their unique features for running large language models outside the NVIDIA ecosystem.
Hands-on testing of Qwen3.8-Max-Preview.
Demonstrates KAT-Coder-Pro V2.5 handling a Seaport app bug fix and water slide coding challenge during the archestra_ai Apps Hackathon.
Covers Kimi K3, Bonsai 27B, Wan Dancer, GPT Red, Ardy, MobileWan, PiD v1.5, Audio to MIDI, GNM, Lucida, Motion4motion, Higgsfield MCP, Robot MMA, Coolfly eVTOL, Robot centaur, Act 2, GenCeption, Wan S
Evaluates Kimi K3 by attempting to remake FF7, Red Dead Redemption, render a human head, create a GTA V clone, and port Inkling to MLX using Inferencer App.
Tests major Gemma 4 update with QAT GGUF, covering tool-calling fix, FA4 support, and vision token control.
Live local testing of Google's Gemma 4 update demonstrates tool-calling fixes, FA4 support, and vision token control on an H100.
Demonstrates wiring OpenCode with speech-to-text and text-to-speech using locally cloned voices, such as Kristen Stewart and Captain Picard, for issuing voice commands and receiving responses.
Covers updates on Claude Code browser, Google Search apps, Gemini Omni, Spotify AI, Kimi K3 benchmarks, Bonsai 27B, Grok agents, ChatGPT search, Apple Watch Siri, Anthropic teachers, OpenAI Codex Micr
Evaluates Kimi K3 via Bridge Horror House one-shot, full-stack builds, and head-to-head BridgeBench V3 arena matches against Fable 5 and GPT 5.6 SOL scored by judges.
Evaluates BottleCap AI's ThinkingCap Qwen 3.6 27B MTP against Base Qwen using Performance, Memory, Agency, OpenAI Human Eval, Sand Physics and Dungeon Crawler tests on a 16GB local setup.
Compares Kimi K3 with Fable 5 and GLM 5.2.
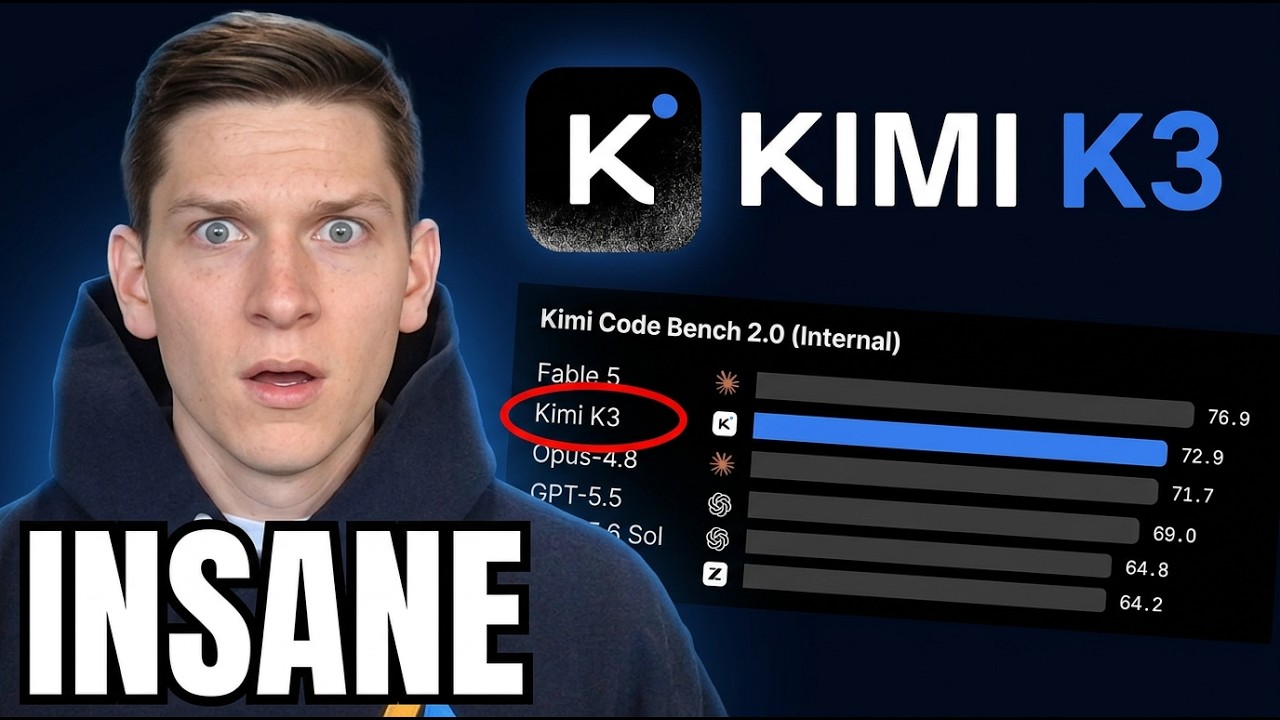
Tests Kimi K3 against GPT-5.6 Sol, Claude Fable 5, and Claude Opus 4.8 using long-horizon coding, frontend, 3D generation, browser agent, and pricing benchmarks.
Tests whether a base 16GB Mac Mini M4 can sufficiently power local LLMs integrated with Pi Coding Agent for actual coding tasks under real-world local AI workloads.
Reviews Kimi K3 through tests involving code, liquid physics, Blender v8 engine, financial explainers, 3D models, Luma Agents, mecha shooters, music composition, cancer detection, finding frogs, deep
Tests n-gram speculative decoding on Qwen 3.6 27B via llama.cpp against MATH-500, LiveCodeBench, and an 18-prompt iterative coding suite using AMD Ryzen 9 9950X and NVIDIA RTX PRO 6000 Blackwell.
Tests Kimi K3 capabilities via browser OS, C++ skate game, frontend design, 3D model print, subway FPS, city timeline, book website, and agent swarm cinema game tasks.
Tests Kimi K3, a 2.8T-parameter model based on Kimi Delta Attention architecture, covering sizing, benchmarks and multiple test results.
Evaluates Kimi K3 via BridgeBench using vibe coding workflows, multi-agent orchestration in BridgeSpace, and production bug fixes, comparing it against Claude Fable 5, GPT 5.6, and Claude Opus 4.8.
Demonstrates enabling the experimental LLM auto-tag feature in the ICE extension via web UI, then automating directory processing using ImageViewer, curl, and Java.
Builds a desktop app extracting text from images and PDFs using Qwen 3.6 locally, demonstrating development workflow and OCR testing without cloud APIs or subscriptions.
PrismML Bonsai 27B binary 1-bit, ternary, and full-precision models are benchmarked on website generation, FPS-style game creation, agentic coding, codebase understanding, and frontend design.
Full Fine-Tuning and LoRA are compared on an Apple M5 Max with 128GB unified RAM using a BERT-based text classification model, tracking RAM usage, training time, and parameter updates.
Flagship-scale models 1-Bit Hy3, Ternary Bonsai, and Colibri are presented as open-source local AI options compact enough for home deployment.
Demonstrates using Vercel's open-source Eve framework to scaffold, run and deploy a data analyst agent via Claude Code and Vercel's plugin, featuring markdown-based configuration, durable execution an
Tests Inkling, a 1T parameter open-weights model from Thinking Machines, across browser workflows, scene generation, C++ game creation, frontend design, roleplay, creative writing, 3D CAD modeling, an
Demonstrates ChatGPT 5.6 features including Codex, Sites, scheduled tasks, logged-in browser research, and the Wolf Control Tower via daily prompt workflows and community-built applications.
Tests Inkling 1T, a general-purpose multimodal model by Thinking Machines.
Demonstrates setting up llama.cpp for multi-GPU support using combined VRAM from merged systems, showing configuration steps and examples of running single or concurrent local LLMs.
Tests an unusual dual-Intel GPU card to evaluate whether achieving 192GB of VRAM in a single PC configuration provides viable performance without requiring NVIDIA pricing structures.
Compares Qwen 3.7 Max and Qwen 35B A3B using Performance, Memory, Agency, Driving Game, Kanban, and Codebase Prompts tests.
Locally installs and tests Ternary Bonsai 27B GGUF, demonstrating full 27B-class reasoning using ternary transformer weights.
Tests PrismML Bonsai 27B using Hermes, OpenClaw, a local coding agent for a Pi extension, and analysis of hundreds of MB of JSONL data to evaluate its capability beyond benchmarks.
Configures Ryzen AI Halo with Ryzen AI Max+ 395 APU for headless inference via multi-user mode, 124GB GTT, performance mode, and disabled IOMMU, demonstrating setup with llama.cpp, vLLM, ComfyUI, Lemo
Demonstrates building documents, slides, websites, data sheets and podcasts simultaneously with one prompt using Skywork's autonomous AI workforce.
Evaluates AI assistants for creative writing across proofreading, literary review, and AI slop risks, while comparing cloud versus local deployment options.
Demonstrates creating seamless location jumps using matching poses and keyframes uploaded into Runway's Seedance 2.0, Kling, or Leonardo to generate smooth transitional clips.
Compares GPT-5.6 Sol and Claude Fable 5 on 3D model creation, an AI magazine project, a retro Mac GTA-style game, an Apple Vision Pro app, and UltraCode gameplay.
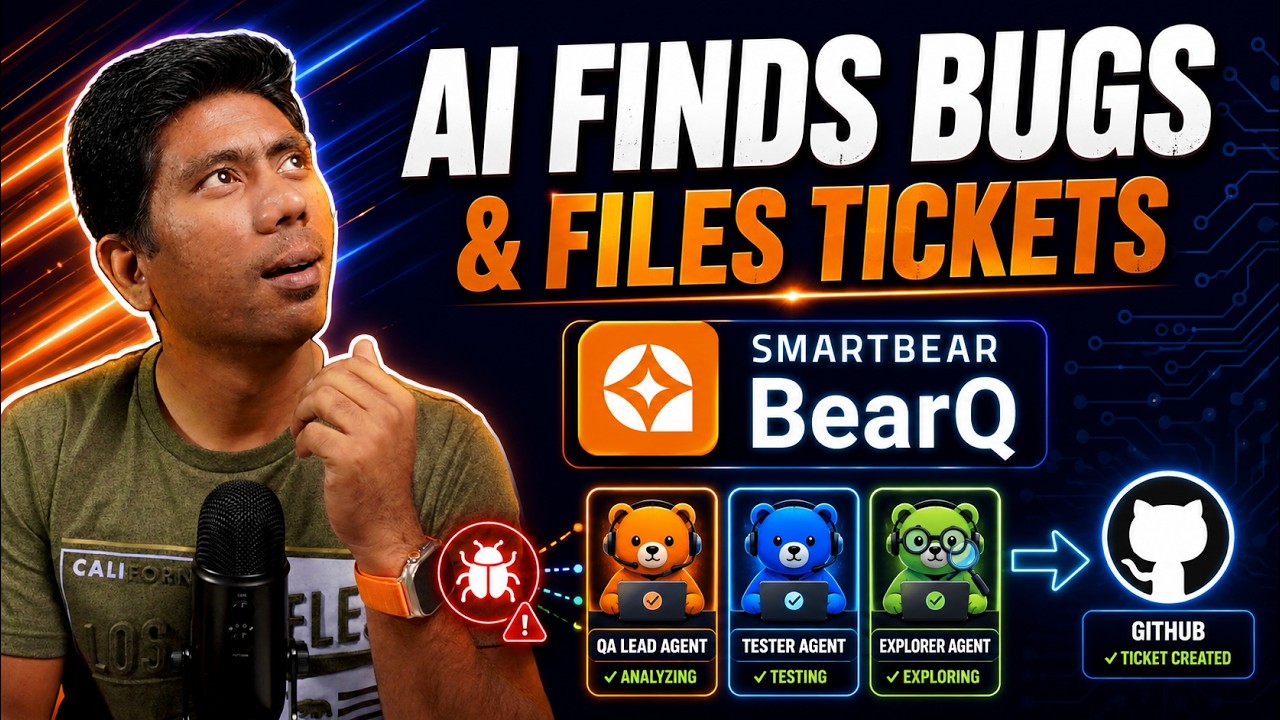
BearQ explores apps, detects issues like missing salary validation, and uses a connected GitHub MCP server to auto-create detailed GitHub issues with reproduction steps.
Tests Meta Muse Spark 1.1 against Claude Opus 4.8, Grok 4.5, and GPT-5.5 via woaibench.ai across coding, agentic workflows, computer use, multimodal reasoning, and long-context tasks.
Installs Colibri and runs full GLM 5.2 locally without GPU using JustVugg/colibri.
Tests Ollama and Llama.cpp running inside Docker on ZimaBoard 2, evaluating speed using Gemma-4 with Vision and GPT-OSS from OpenAI, plus an endurance thermal throttle check.
Locally installs and tests OpenLumara, a modular, token-efficient AI agent framework written from scratch.