DeepSeek V4 Flash Fully Local — 32 tok/s on a Single Chip
Runs the 284B parameter DeepSeek V4 Flash model locally on an AMD Ryzen AI MAX+ 395 with 128GB unified memory using the Lucebox inference engine with DSpark speculative decoding.
Videos
Find videos about LLM models, hardware, runtimes, benchmarks and practical AI workflows.
Runs the 284B parameter DeepSeek V4 Flash model locally on an AMD Ryzen AI MAX+ 395 with 128GB unified memory using the Lucebox inference engine with DSpark speculative decoding.
Qwen 3.5 4b remains the best 4 billion parameter model among Nanbeige, Qwen, LocoOperator, Llama and Opus finetunes.
Compares Laguna S 2.1 and Qwen 3.6 35B-A3B on an RTX 3060 using llama.cpp, evaluating debugging accuracy and animation generation tasks via manual testing.
Tests Claude Opus 5 via image to 3D, financial videos, Luma Agents, Blender, music, FROG TEST, cancer identification, deep research, specs, costs, benchmarks and guardrails.
Tests Firstmate coordinating Claude Code, Codex CLI, Pi, OpenCode and Grok Build via Herdr, managing parallel tasks, Git worktrees and worker recovery.
Tests whether two AMD Ryzen AI Halo systems can run a 400B parameter model, evaluating local large language model inference performance on consumer hardware.
Demonstrates LingBot-World 2.0 using causal pretraining, MoBA attention, and agents for real-time interactive world generation at 720p 60fps via 14B and 1.3B models.
Tests OvisOCR2, a compact 0.8B end-to-end model for page-level document parsing.
Covers Claude Opus 5, Gemini 3.6, Qwen 3.8, Flux 3, Qwen Image 3, Laguna S2.1, Mage Flow, ShotPlan, Homie, OpenAI hack, ChatGPT Health, GLM with vision, GPT live voice, Google quantum breakthrough, Na
Evaluates Inferencer Labs' Macaron-V1 LoRA for GLM-5.2 on an M3 Ultra 512GB using music generation, human anatomy, game development tasks and photorealistic face creation tests.
Tests Upstage’s 250B-A15B open-weight model for office productivity and document-intensive work.
Kimi produces high-quality front-end website design output but suffers from slow generation speeds due to limited compute resources.
Compares Opus 5 with Kimi K3 on hard coding tasks.
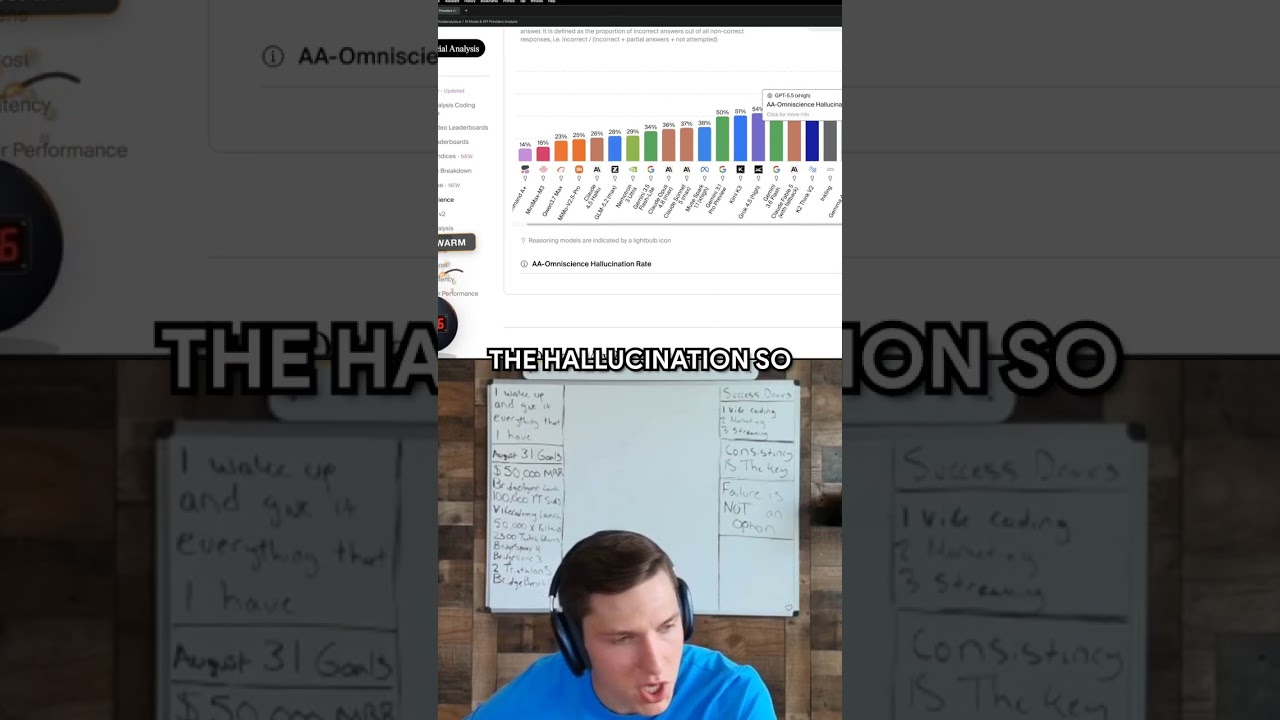
Compares hallucination rates of GPT 5.6, GPT 5.5, and GPT 5.6 Tera against Fable 5, Grok 4.5, Kimi K3, and Minimax, noting higher rates for GPT models.
Tests Claude Opus 5 against Fable 5, GPT-5.6 Sol, and Kimi K3 via World of AI Bench, ARC-AGI-3, Artificial Analysis, coding, reasoning, and game dev demos.
Evaluates Claude Opus 5 via browser OS tests, C++ skate game, frontend design, Subway FPS, UltraCode City Timeline, and Street Yeet game creation tasks.
Compares Laguna XS 2.1 and Qwen3.6 on Apple Silicon via setup, speed, token throughput, response quality, reasoning, and tool-use accuracy for real agentic coding tasks.
Tests Intern-S2-Preview-397B, InternLM's most capable multimodal foundation model for scientific intelligence.
Evaluates Claude Opus 5 via BridgeBench V3 against Fable 5, GPT 5.6 SOL, Kimi K3, and Grok 4.5 using Claude Code, BridgeSpace multi-agent orchestration, and production bug fixes.
Covers Kimi K3 launch, US sanctions threat against Chinese AI models, OpenAI Hugging Face security incident, Gemini 3.6 Flash models, Qwen3.8 open-weight release, ChatGPT health features, Claude voice
Evaluates Fish Audio's Free for Devs AI Text to speech and voice cloning tools for their ability to generate realistic human emotion.
Evaluates Kimi K3 against Opus 4.8 and Kimi K2.7 on real engineering tasks using a custom benchmark suite scoring seven dimensions, revealing higher failure rates for complex tasks despite strong perf
Tests Poolside Laguna S2.1 performance in browser workflows, C++ game creation, FPS development, creative writing, website design, fan fiction, 3D printer simulation, and frontend testing.
Tests Tess-4 27B against unsloth/Qwen3.6-27B-MTP-GGUF using Performance, Memory, Agency, OpenAI Human Eval, Sand Physics, Dungeon Crawler, Blender and Godot benchmarks.
Evaluates Qwen-Audio-3.0-TTS for content consistency, speaker similarity, prosodic naturalness, audio quality, controllability, multilingual coverage, efficiency, and robustness.
Tests Laguna S2.1 using Inferencer App v2.2.2 on M3 Ultra 512 GiB against DeepSeek and GLM based on benchmarks claiming superiority.
Tests Ling-3.0-flash, a hybrid-reasoning MoE model designed for production-scale agentic applications.
Evaluates Qwen 3.8 cloud preview by converting a Local-OCR prototype built by Qwen 3.6 into a finished application featuring a progress bar, page counter, and streaming Result tab.
Benchmarked a hidden local AI model in macOS 27 on a $10,000 Mac Studio to evaluate its speed performance.
Demonstrates spec-driven development versus one-shot YOLO prompting for local LLMs by creating a detailed specification and multi-stage plan to build an Asteroids clone named SuperAsteroids.
Local installation and testing of the Nanbeige4.2-3B compact agentic model.
Poolside Laguna XS 2.1 achieves 70.9% on SWE-bench Verified and 63.1% on SWE-bench Multilingual with a 262K context window.
Tests Laguna S 2.1's real-world coding capabilities and benchmarks performance against GLM 5.2, Qwen 3.7 Max, Hy3, and Kimi K3 using Woaibench.
Examines applying negative logit penalties to reduce reasoning tokens in Qwen3.6-27B, GLM-5.2, and Tencent Hy3 via vLLM, referencing ThinkingCap and Meta FAIR research.
Demonstrates using Docker Sandboxes to isolate coding agents like Claude Code in a local microVM, preventing unauthorized access to the host filesystem, databases, and SSH keys.
Tests Gemini 3.6 Flash and introduces 3.5 Flash-Lite and 3.5 Flash Cyber from Google.
Compares two nearly identical gaming laptops differing in VRAM to evaluate local AI performance limits.
Installs and tests Laguna S 2.1, an 118B MoE model designed for software engineering and agentic coding use cases.
Evaluates Qwen 3.6 14B A3B FableVibes against Qwen3.6-35B-A3B using Performance, Memory, Agency, OpenAI Human Eval, Sand Physics and Dungeon Crawler tests on a 16GB local setup.
Tests Intern S2 Preview 397B MLX Q9 against Claude and Kimi K3 using Inferencer App v2.2.2 on Mac Studio M3 Ultra 512 GiB for scientific research tasks.
Demonstrates setting up Hermes Agent with Qwen 3.5B via Ollama and LM Studio with Locally on Mac Mini M4, plus comparing local model speed against an M5 Max MacBook Pro.
Installs Colibri and demonstrates running Tencent Hy3 locally using disk, CPU and GPU resources.
Tests Gemini 3.6 Flash against browser workflows, C++ games, FPS dev, frontend design, timelines, writing, 3D models, and Android apps.
Demonstrates tuning a dual-GPU local LLM setup using llama-server startup options, layer split, tensor split, and multi-token prediction to increase tokens per second.
Demonstrates TestSprite CLI integration with Claude Code, Cursor, Cline, and Codex agents to enable self-verification of generated code within a real browser environment.
Installs Colibri to shrink the full GLM 5.2 locally without GPU.
Installs and tests catmind-1.2b, a LoRA-fine-tuned model whose think block outputs a short, query-unrelated cat story instead of actual reasoning.
Evaluates Inkling MLX Q3 using Inferencer App v2.2.1 on M3 Ultra 512 GiB across maths, safety, vision tasks, gaming simulations, image inference and audio capabilities.
Qwen, Ornith, Qwythos, and Gemma 4 compete in a two-round battle using easy and challenging prompts to demonstrate the importance of writing a good prompt.
Tests Qwen3.8 MAX Preview on browser workflows, subway scenes, FPS dev, C++ games, 3D CAD, microcontrollers, and city timelines via practical coding and reasoning tasks.