Local Qwen3 35B + TestSprite MCP Server — AI Testing for FREE
Connects local Qwen3 35B via LM Studio with TestSprite MCP Server in VS Code to execute complete front-end automation tests entirely offline.
Videos
Find videos about LLM models, hardware, runtimes, benchmarks and practical AI workflows.
Connects local Qwen3 35B via LM Studio with TestSprite MCP Server in VS Code to execute complete front-end automation tests entirely offline.
Locally installs dots.tts, a 2B-parameter fully continuous, end-to-end autoregressive text-to-speech system.
Evaluates GLM 5.2 performance using Inferencer App on M3 Ultra 512GB across photorealism, sound generation, 3D game dev, coding, maths, logic tests and AI safety.
Demonstrates building a TypeScript app running Pi (on Kimi) in a loop with an orchestrator spinning up parallel worker agents, storing runs in a database via the Agent Control Plane dashboard.
Locally installs LoopCoder-v2, a 7B instruction-tuned code model based on the Parallel Loop Transformer (PLT), sourced from Multilingual-Multimodal-NLP on Hugging Face.
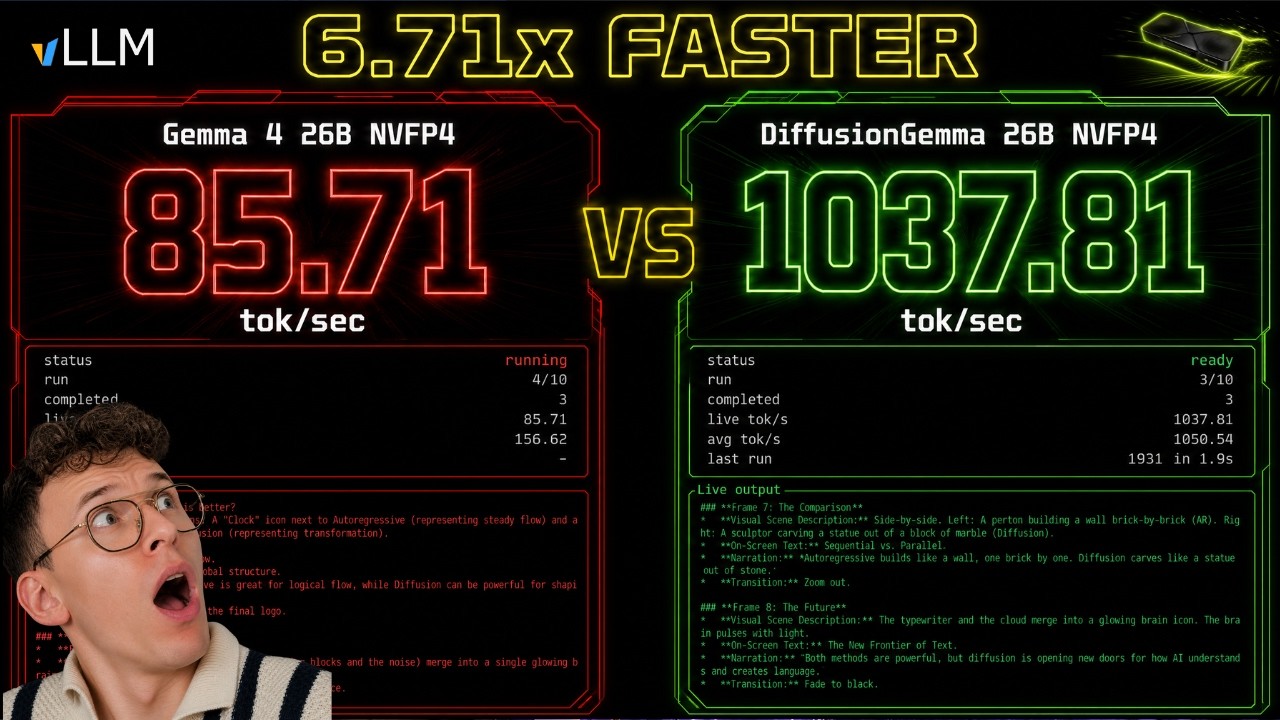
Deploys DiffusionGemma 26B-A4B in NVFP4 with vLLM on RTX PRO 6000, benchmarking its 256-token parallel generation against standard Gemma 4 to demonstrate a 6.73x speedup.
Project Odysseus installation on M3 Mac using Ollama compares Gemma 3 12B and GPT 5.5 via deep research, brain memory, model comparison scoreboard, and image editor features.
Evaluates GLM 5.2 using Ollama Cloud and the Pi agent on three coding tests: a sorting algorithm, six algorithms with visualization, and a Hantavirus simulation in Rust, checking first-time compilatio
Demonstrates Luce KVFlash recalling a hidden fact within a 256K token novel-length prompt while paging most context off the GPU to conserve VRAM.
Tests Kimi K2.7 Code against Opus 4.8 Max, GPT-5.5, Fable 5, Qwen 3.7 Max, and Grok 4.3 using World of AI benchmark and a strange attractors coding test judged by GPT-5.5 Pro.
Reviews GLM 5.2 capabilities including digital earth, animation, 3D models, ray tracing, music composition, math animation, deep research and specs.
Installs and tests VibeThinker-3B, a 3B-parameter model from the VibeThinker series hosted on Hugging Face under WeiboAI.
Demonstrates setting up Hermes Agent by installing the software, connecting an LLM, verifying configuration using hermes doctor, executing a test session, and listing subsequent utility commands.
Evaluates OpenRouter Fusion against Claude Fable 5, GPT-5.5, and Claude Opus 4.8 using Browser OS, C++ Skate Game, Deep Research, and Frontend tests under quality and budget settings.
Qwen 3.6 27B non-MTP versus MTP variants are compared for performance, memory usage, agency capabilities, and coding skills on a system featuring 16GB VRAM and 32GB DDR4 RAM.
Demonstrates running DFlash with SGLang's Spec V2 overlap scheduler on Qwen3.6-27B, achieving 160 tok/s on a single H100 via installation, benchmarking, and performance measurement.
Locally installs gemma-4-12B-coder-fable5-composer2.5-v1-GGUF and tests it with hermes agent.
Qwopus3.6-27B-Coder-MTP and Qwen3.6-27B-MTP build a multi-phase LAN whiteboard app with drag-and-drop images, real-time chat, and advanced features on separate fresh VPSs.
Demonstrates DeepSeek V4 Flash inference on AMD Strix Halo via ds4 and ROCm/HIP, covering Q2/hybrid 4-bit configs under 128GB RAM, multi-node 4-bit clusters, and benchmarks against SWE Bench Mini.
Demonstrates Omnigent orchestrating Claude Code for implementation and Codex for code review within separate git worktrees, featuring multi-model debate and cross-device session continuity.
Demonstrates fitting a model's full 256K context on a small GPU using Luce KVFlash by keeping a tiny KV pool on the card and paging the rest to RAM.
Demonstrates creating autonomous Claude agents using Base44 Superagents to automate workflows like research, emails, and scheduling without code, hosting, or complex integrations.
Tests MiniMax M3 in Claude Code UltraCode Mode against GPT-5.5 via large codebase review, Pi /goal extension build-off, and Splunk cyber CTF challenge.
Tests SenseNova-U1-Infographic, an open source multimodal interleaved image and text generation model scoring highest among current open source models, on Mac and Windows.
Compares GLM-5.2 and Kimi K2.7 on real coding tasks within the Hermes Agent environment through a live demonstration.
Demonstrates Diffusion Gemma via KB-Diffusion, testing local performance through speed comparison testing and quality comparison testing against other examples.
Reports GLM-5.2, DiffusionGemma, Fable 5 updates, OpenAI Codex changes, Cursor Auto-review, and 1X Technologies NEO humanoid robot production.
Covers GLM 5.2, Kimi K2.7, Claude Fable Mythos ban, SCAIL 2, MiniMax M3, Nexus N2, Dots tts, World Tracing, Flex4DHuman, VideoMDM, Surflo, Moverse, i1, AnchorWorld, MeshFlow and Millivid.
Hands-on testing of GLM-5.2 from Z.AI covers architecture analysis and execution of two coding tasks.
Evaluates Kimi K2.7 Code performance using Inferencer App on M3 Ultra 512GB, comparing local, clustered, and cloud inference against Claude Max across sound, photorealism, coding, vision, logic, and m
Tests GLM-5.2 on browser OS, C++ games, subway scenes, frontend design, 3D printer simulation, CAD, MotoGP games, and drum kits via practical coding, simulation, and design tasks.
Evaluates GLM-5.2 via video editing, Splunk Cyber CTF challenge, and Mario Clone game creation, comparing results against MiniMax M3.
Tests Qwen 3.6 27B MTP versus Qwopus 3.6 27B v2 MTP using an Expense Tracker, Card Matching Game, Breakout Game, and 2D Driving Game on a system with 16GB VRAM and 32GB DDR4 RAM.
Runs DiffusionGemma via llama.cpp on RTX 3060, achieving ~44 tok/s with MoE offloading and quantization. Covers diffusion text mechanics, strengths in code/OCR/Sudoku, and local setup steps.
Tests MiniMax M3 within MiniMax Code, demonstrating its role as an agentic coding workflow with features like multi-agent teams, output verification, and automated task execution.
Hands-on review of Kimi K2.7 Code, a coding-focused agentic model, demonstrating its capabilities through two distinct coding tasks.
Qwen3.6 27B and Claude Fable 5 build an LLM benchmark dashboard on a fresh local VPS connecting to llama-swap endpoints to run benchmarks and display results.
Installs and tests Nemotron 3.5 ASR, described as a multilingual, streaming model.
Evaluates Kimi K2.7 Code via browser OS tests, subway scene and FPS tests, C++ skate and rally games, frontend design, multimodal item design, 3D printer simulation, and image to SVG conversion.
Covers Claude Fable & Mythos 5, Cube Basher, Apple Intelligence, Siri AI, NotebookLM, Gemini Live Translate, DiffusionGemma, policy manifestos, ChatGPT email sending, OpenAI S-1 filing, SpaceX IPO, Co
Demonstrates connecting Browserless Agent and GitHub Agent to SmartBear BearQ via MCP for CI triggers, PR reading, and browser automation within autonomous QA workflows.
Installs and tests Luce Spark to run a 35B model on a 16GB GPU, fitting it in just 14 gigs.
Demonstrates a workflow using Claude Fable 5 for planning, architecture, and system design, then handing off to GPT-5.5 for execution, code generation, and debugging.
Evaluates Macaron-V1 LoRA for GLM-5.1 against Claude using Inferencer App on M3 Ultra 512GB across coding, maths, logic, thinking, photorealistic face generation and Flappy Birds tasks.
Reviews and tests Nex-N2, an agentic model designed for real-world productivity scenarios.
Rudimentary reasoning and simulated agency tests evaluate DiffusionGemma on a local system with 16GB VRAM and 32GB DDR4 RAM, discussing its pros and cons as a new token generation technique.
Tests Nex-N2 Pro against GPT-5.5, Claude Opus 4.7, DeepSeek V4 Pro, and Gemini 3.5 using World of AI Benchmark, coding tasks, and demos.
Locally installs and tests DiffusionGemma GGUF using llama.cpp diffusion.
Reviews Claude Mythos 5 and Fable 5 against GPT 5.5, demonstrating ray tracing, earth simulation, 3D reconstruction, music composition, mecha shooter generation, chemistry courses, cancer classificati
Setup guide for running DiffusionGemma locally using vLLM nightly builds and transformers 5.11.0, demonstrating generation of playable games and applications.