
Video
Fahd Mirza
2026-09-11
Run 35B Model on Phone Under 3GB Memory with Edge0
Introduces edge0, an open-source streaming MoE inference framework.
Videos
Find videos about LLM models, hardware, runtimes, benchmarks and practical AI workflows.
Introduces edge0, an open-source streaming MoE inference framework.
Demonstrates DeepSeek V4.1 Flash hallucinations in agentic cybersecurity and coding, explains sparse attention's role in missed context, and shows methods to reduce errors using the AA Omniscience Hal

Explains DeepSeek V4.1 Flash using DeepSeek Sparse Attention and Compressed Sparse Attention 2 to limit reads to 640 entries per layer with an 890-byte KV cache per token via the lightning indexer.

Covers ChatGPT Images 2.5, Meta Muse, DeepSeek-V4.1-Flash, Anthropic warnings, OpenAI updates, Apple announcements, MAI-Image-2.6, Gemini App, Suno, Lyria 3.5, and DaVinci Resolve 21.1.

Demonstrates LiteLLM Auto Router with Pi Coding Agent, Ollama, and oMLX on Apple Silicon, comparing heuristic versus LLM classifiers for Qwen3.5 4B, Gemma 4, and Qwen3.8 27B.
Tests Nail Qwen3.6-35B-A3B-GGUF-MTP via Performance, Memory, Reasoning, OpenAI HumanEval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot on a 16GB local setup.

Compares Halogen Flash Server, EngramHalo and ROCm/Vulkan llama.cpp for Qwen3.8-Flash-Next on AMD Strix Halo via Terminal Bench Mini agentic tasks and speed benchmarks.

Locally installs OUI-1, identified as the first diffusion model built for generative UI.

Runs DeepSeek-V4.1-MLX-Q4i via Inferencer v2.2.8 on Mac Studio M3 Ultra 512, testing math, coding, logic, office apps, canvas animations, 3D simulations, games, and image generation.

Tests Ling-3.0-flash-VL, described as a native multimodal model.

Demonstrates RAG ingestion using LangChain, RecursiveCharacterTextSplitter, embeddings, and Qdrant via Docker, covering chunk sizing, cosine similarity, and metadata filtering.
Evaluates DeepSeek V4.1 Flash via browser OS tests, C++ skate and rally games, robot arm control, Subway FPS, Blender & Godot wrestling, 3D CAD models, and watch website design.

Demonstrates exposing TTS engine tuning parameters in TalkWithMe using Chatterbox, IndexTTS, and tts-serve to imbue emotion into cloned voices.

Installs and tests Nex-N2.5 mini, an agentic model, using RunPod for GPU compute.
Reviews GPT Image 2.5 against GPT Images 2 and Nano Banana 2, demonstrating sketch features, multi-turn editing, transparency, typography, spatial understanding, reference consistency and specs.

Demonstrates using Archon and SonarQube Cloud in a workflow where Sonar acts as a non-skippable security gate to catch vulnerabilities in AI-generated code before shipping.

Tests DeepSeek V4.1 Flash by building a 3D Viewer, catching an ATC bug, and solving physics problems from scratch.

Dirk, identified as Qwen 3.8 27B with modified templates, is benchmarked against Qwen 3.8 on Bob-bench to evaluate its actual performance capabilities.
Tests GLM-5.3-Flash 320B on M5 Max against Qwen3.8-Flash-Next via MTPLX, .NET migration, and SVG generation, analyzing quantization effects on memory, accuracy, and KLD.
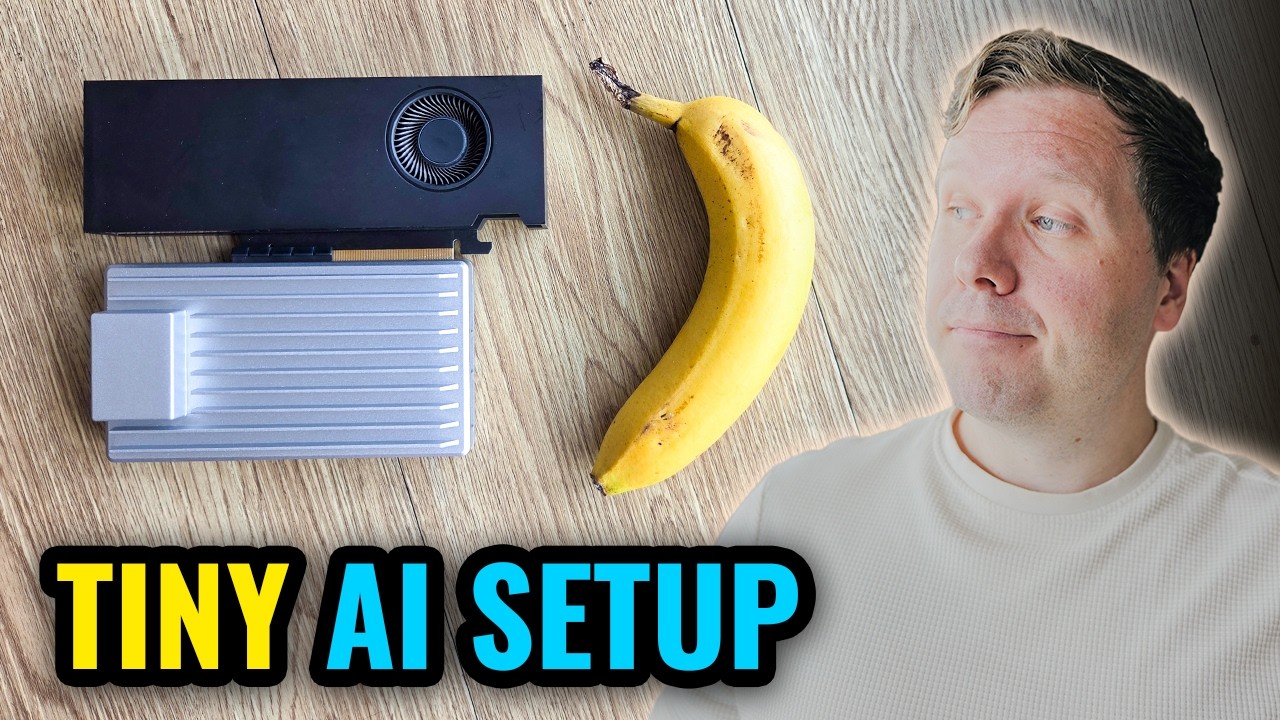
Runs Gemma4 E4B and Qwen 3.8 27B on ZimaBoard 2 using llamacpp, comparing performance with an added RTX 2000 GPU through Kanban, Sand Physics, and Dungeon Crawler demos.

Tests Gemini 3.8 Flash performance in browser workflows, C++ game development, frontend design, FPS generation, robot arm control, and Blender and Godot workflows.
Tests DeepSeek V4.1 Flash on coding, 3D simulations, Three.js, games, agentic tasks and vision, noting speed of 300–400+ tokens per second and pricing against frontier models.
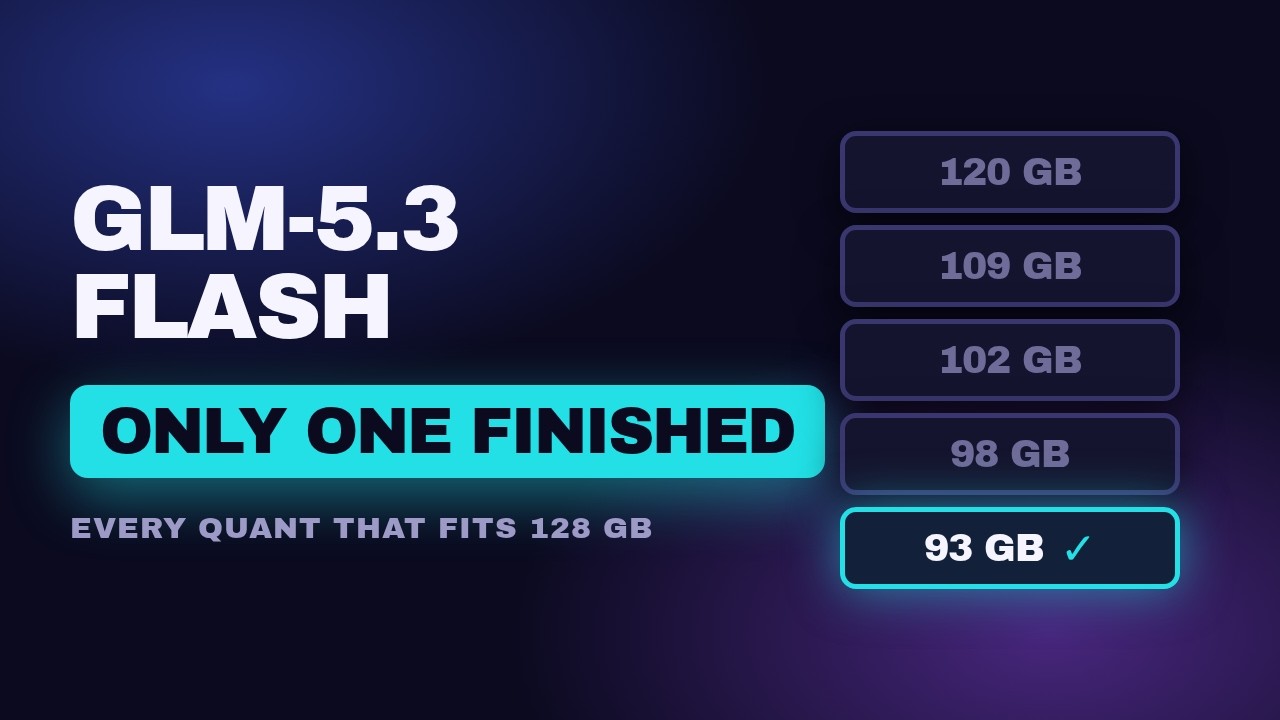
Tests Unsloth quants of GLM-5.3-Flash on GMKtec EVO-X2 using llama.cpp across four one-shot tests at low, high, and max reasoning settings.

Locally installs and tests zg (zvec-grep) powered by zvec, which unifies ripgrep, BM25, and vector search.
Evaluates GLM 5.3 MLX Q4i on Mac Studio M3 Ultra across Low, High, Max and MinMax thinking modes using coding tasks and complex simulations.
Ranks local coding LLMs into tiers based on quality, size relevance, and efficiency, covering Qwen variants, Dirk, OLMo, and others across different GPU constraints and quantizations.

Compares Qwen3.8-Flash-Next inference via llama.cpp, SGLang, and FreeToken on RTX PRO 6000 Blackwell using AIPerf, measuring first-token latency, decode speed, accuracy on GSM8K/MATH-500, and startup

Demonstrates building a LangChain agent using create_agent with multiply and web search tools, comparing invoke versus stream modes, measuring token usage, applying ModelCallLimitMiddleware, and enabl

Compares Oh My Pi with Pi and OpenCode through initial setup, configuration tweaks, built-in tools, custom system prompts, compaction methods, sub-agents, and design philosophy analysis.
Tests MiniCPM5-2B in GGUF format, identifying it as the second model in the MiniCPM5 series hosted on Hugging Face under openbmb.

Tests MiniCPM5-2B locally.

Locally installs and tests ISTA-DASLab Qwen3.8-27B-GSQ-RCO-GGUF models using GSQ and RCO quantization methods.

Runs local LLMs like Qwen3.8, GLM-5.3 Flash, Gemma, Muse/Glimmer and coding agents Pi, Codex via LM Studio, oMLX, MTPLX, Ollama, llama.cpp on M5 Max.
Compares GPT-6 Astra and Claude Fable 5.1 using Hot Wheels physics simulation, Vision Pro FPS task, robot arm control, software efficiency, and Steve PC game build tests.
Tests Tiel Coder 35B A3B performance, memory, reasoning, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot on a 16GB local setup.
Tests Ponytail, a Claude Code plugin, on real coding tasks to evaluate its ability to reduce generated code volume by up to 94% while maintaining functionality and quality.
Checks whether GPT-6 Astra represents the arrival of AGI.
Reviews GPT 6 Astra capabilities across physics, ray tracing, Unreal video games, drawing, sprite animation, music composition, VR real estate, product commercials, math explainers, image identificati
Demonstrates Qwen3.8-Flash-Next on 4x RTX 3090s using DeepSeek Harness with MiniMax H3 for autonomous music video creation, comparing throughput against Qwen3.8-27B.

Benchmarks unsloth/Qwen3.8-Flash-Next-GGUF on RTX 3060 using llama.cpp and thecodacus/spec-wins coding lab with contradictory specs and decoys.

SkillSpector detects vulnerabilities, malicious patterns, security risks, prompt injection, data exfiltration, and supply-chain risks in AI agent skills.
Benchmark Qwen 3.8 27B Q4_K_M via llama.cpp on MacBook Pro M5 Max versus RTX 5090, analyzing memory usage, GGUF headers, KV cache behavior, and MTP drafting performance at 8K context.
Locally installs and tests OmegaClaw, a neural-symbolic agent framework based on the Hyperon AGI stack.

Demonstrates GPT-6 Astra use cases including one-shotting games, controlling computers via OpenAI's upgraded harness, building 3D environments in Blender and Unity, and operating real-world robots.

Covers GPT 6 Astra, Claude Fable 5.1, Gemini 3.8 Flash, Muse Spark 1.3, H3 World, SolarWM, TimesFM, Lucida, VideoDeltaNet, LLaDA image, Deepseek v4 flash vision, Qwen 3.8 0902, WeatherNext 3, Fly brai
Locally installs and tests Spark-X2.5-4B to evaluate its capabilities for making AI practical, efficient, and accessible.

Demonstrates converting Python functions to LangChain tools using the @tool decorator, binding them via bind_tools, executing calls through .invoke(), and returning results as ToolMessage for USD to I
Introduces Extropic Z1T, a family of transformer-like AI models designed for the Z1 chip rather than GPUs.

Tests Hy4 Preview against GLM 5.3 using Inferencer App Q4-INF quantization on Mac Studio M3 Ultra 512 GiB via thinking mode performance, UI testing, censorship checks, complex code modification, game

Runs GLM-5.3-Flash 1-bit via Unsloth and llama.cpp on GMKtec EVO-X2, testing Blockfall, Eruption, Blind Artist, and The Ledger with 9.2–9.6 tok/s performance.