AI News: 6 New Models & A Nano Banana Killer
Tests Krea 3 image editing, benchmarks Gemini 4 Argon and Meta Muse Wonder, and covers FLUX 3 Image Klein, Qwen-Image-2.1-Turbo, Microsoft MAI-Base-2, NVIDIA Nemotron 3.5, Ultramarine 1 Flash, OpenAI
Videos
Find videos about LLM models, hardware, runtimes, benchmarks and practical AI workflows.
Tests Krea 3 image editing, benchmarks Gemini 4 Argon and Meta Muse Wonder, and covers FLUX 3 Image Klein, Qwen-Image-2.1-Turbo, Microsoft MAI-Base-2, NVIDIA Nemotron 3.5, Ultramarine 1 Flash, OpenAI
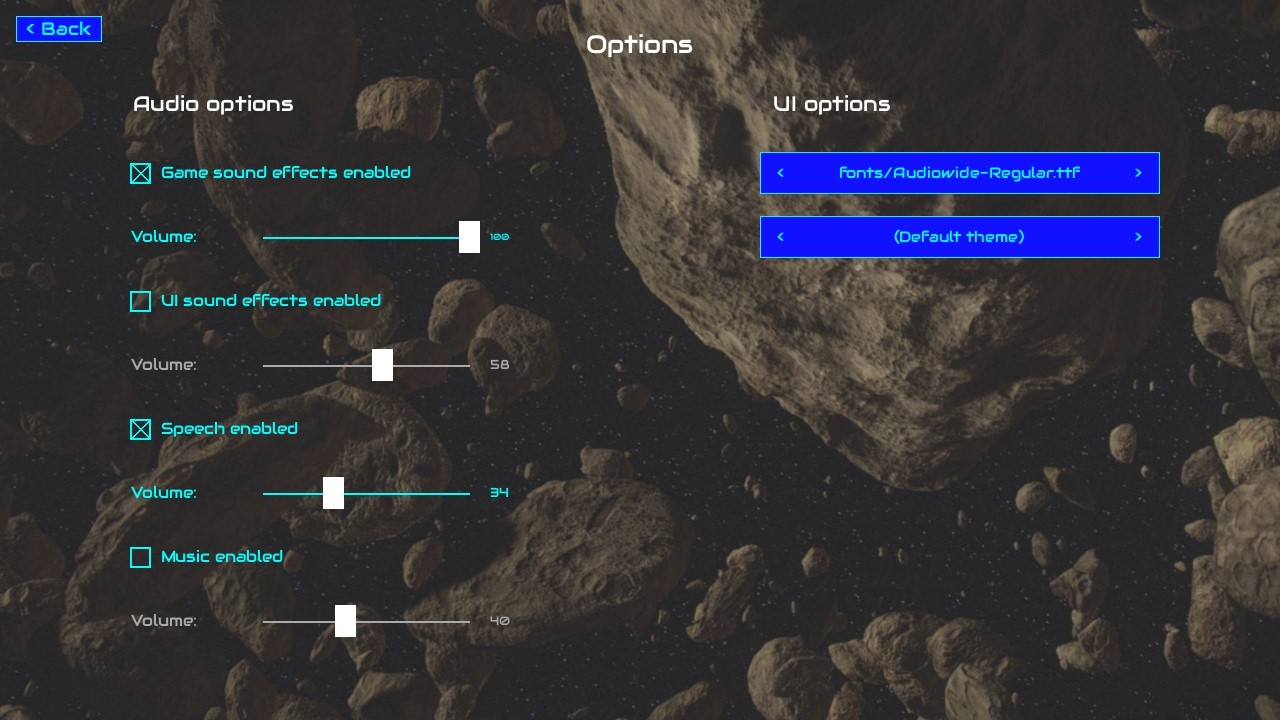
A spec-driven vibe coding experiment uses a local LLM to build Dust to Dominion, implementing the Options screen and wiring up controls.
Demonstrates replacing autonomous dark factories with an AI software factory using upfront planning, parallel issue processing, and staging tests via the open-source ai-software-factory project.
Integrates Strata Metal Inference Engine with Pi Coding Agent to perform .NET migrations, code fixes, UI modernization, and application execution using Qwen3.8-Flash-Next on an Apple M5 Max.
Tests Qwen3.8 27B Q4 on Blender and Godot, evaluates Qwen3.8 Flash Next via Strata, and compares local performance against Claude Opus 4.6 using an ASUS ROG system with RTX 5090.
Evaluates Qwen Image 2.1 using a custom test suite to identify strengths and weaknesses across various image generation tasks.
Benchmarks Qwen3.8 27B and Flash Next on single/dual AMD Radeon AI PRO R9700 using GGZ14, Radiance, R9V, tcclaviger vLLM, llama.cpp and vLLM via AI Toolbox Cockpit.
Locally tests the 9B-class vision-language model Bonsai 2 Ternary 9B with ternary transformer weights using prompts involving Nadsat, 28 languages, scientific reasoning, and comedy sketches.
LoRA fine-tunes Qwen 3.5 0.8B using Apple MLX on a MacBook Pro with Apple M5 Max, improving text-to-SQL accuracy from 44 to 90 out of 100 in 9 minutes.
Tests Kolibri MLX Q9 using Inferencer v2.4.5 on Mac Studio M3 Ultra 512 against Mistral, GLM-Air and Qwen-35B across mathematics, coding, logic and German output tasks.
Tests Grok Voice 3.0.
Tests Liquid AI LFM2.5-24B-A2B MoE model on Mac mini M6 via LM Studio and OpenClaw with 128K context, noting activation of ~2.45B parameters per token.
Tests MiniCPM-V 4.7 against 29 tasks across OCR, object recognition, charts, reasoning, video, and browser actions, comparing performance with the 35B variant using triple-run evaluations.
Locally installed LFM2.5-24B-A2B is tested via DairyFlow app bug fixing, tattoo simulation, an 81-language test, deep sea submarine physics, and a secret wedding scenario.
Demonstrates an AI content engine using Apify, deduplication filters, and Jev to curate daily digests, plus provides the build-signal-engine skill for automated setup via interview.
Hands-on local tutorial demonstrating REA to reverse engineer anything using agents, covering analysis from app behavior down to native binaries via the morluto/rea repository.
Demonstrates running Claude Code locally on Windows via Ollama using models like Qwen 3.8 27B, covering installation, configuration, and usage examples such as writing expenses.py.
ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder is evaluated via performance on RTX 2000 16GB, memory, reasoning, HumanEval Remix, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot.
Tests whether Qwen 3.8 Flash Next Coder uses less memory than Qwen 3.8 Flash Next through head-to-head coding challenges using Strata.
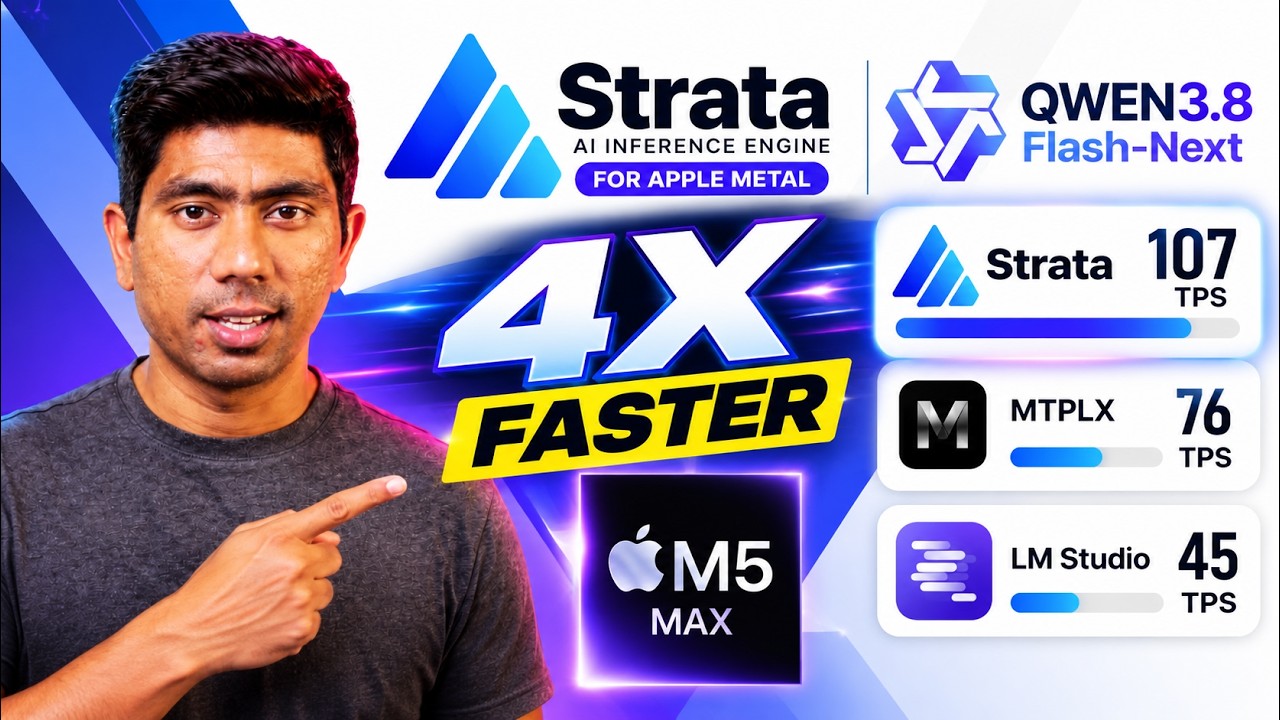
Tests Strata, an open-source AI inference engine with native Apple Metal backend, against LM Studio using Qwen3.8-Flash-Next on Apple M5 Max with 128GB unified memory.
Argon is tested using a Bihari Kebab Simulation and examples to demonstrate its capabilities for deep work.
Locally installed GGUF quantized MiniCPM-V 4.7 1B via Ollama and llama.cpp undergoes clock time, simulation, soldier vision, bridal dress, handwritten multilingual, math tests and benchmarks.
Tests Gemini 4 Argon performance in browser workflows, C++ game dev, Peri Robot arm control, FPS gen, Blender/Godot usage, reverse engineering, and motion video creation.
Gemini 4 Argon is benchmarked via WoAI Bench against Claude Opus 5.5 and GPT-6 Astra in coding, 3D generation, SVG animations, and multimodal reasoning.
Installs DeepSeek Harness on Windows via Ollama using Qwen 3.8 and Gemma 4, demonstrating file sorting and workout report generation while configuring workspaces and fixing API errors.
Compares KV cache methods for VLM coding agents on DGX Station GB300, DGX Spark, and RTX Pro 6000, evaluating latency and throughput with no cache, VLM prefix cache, CPU offload, and LM Cache.
Hands-on tests evaluate Gemini 4 Argon via coding games, scheduling, research tasks, 3D printing Gary Busey, and teaching a robot to play cornhole, comparing results against Claude and ChatGPT.
Compares Claude Haiku 5.5 and local Qwen 3.8 27B using Pi agent across four real tasks, evaluating cost versus performance on an AMD Radeon Pro W7800 GPU.
Tests Muse Wonder using Blender, Godot, DeepSWE benchmark, Oracle 8i SQL bug hunting, vision tasks, and translation across 80+ languages.
WoAI Bench evaluates Meta's Muse Wonder Full against Claude Opus 5.5, Claude Fable 5.1, GPT-6 Astra, and SWE 2 in coding, frontend development, 3D game generation, SVGs, and motion graphics.
Meta Muse Wonder is tested against Claude Opus via browser workflows, C++ game dev, pool games, Peri Robot arm control, frontend design, and FPS development, plus improvement tasks.
Seeed Studio reBot Arm B601 executes tasks via Qwen3.8-Flash-Next reasoning, Meta SAM 3.1 vision, and a Jev-like decision model using plain-English voice instructions.
Locally installed MiniCPM-V 4.7 35B-A3B is tested on coding, SQL debugging, handwritten note OCR, physics reasoning and 80-language translation alongside benchmarks.
Installs Ollama on Windows, runs models locally via PowerShell, tests CPU performance, manages libraries, adjusts settings, and demonstrates offline image analysis.
Tests Step 5 Preview, StepFun's 600B-parameter MoE model, on browser workflows, C++ game dev, FPS gen, Blender, Godot, frontend design, and OSRS.
Evaluates software development skills using the 2x test against REA capabilities, explaining why reverse engineering succeeds while warning against the meat proxy trap of relying solely on AI agents.
Demonstrates full-duplex voice AI using Qwen3.6-35B-A3B on RTX 3060 via 0.6s micro-turns and LoRA fine-tuning, based on DuplexCascade.
Tests Mirai Uzu against MLX, oMLX, llama.cpp, and MTPLX on M5 Max and M6 Mac mini using speculative decoding and Metal GPU kernels.
Evaluates bottlecapai/ThinkingCap-Qwen3.8-27B-GGUF via Performance, Memory, Reasoning, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender, and Godot tests.
Tests MiniMax M3.1-Flash-Preview via mcode on Ubuntu using drone vision decisions, a Blender and Godot game, and debugging a legacy DB2 materialized query table.
Tests Microsoft-Decision-1 using a Blender and Three.js bespoke suit configurator and SQL debugging tasks.
A roundup covering new developments in artificial intelligence, mathematics, biology, materials science, robotics, and various software tools released recently.
Locally installs and tests Underdog Saluki 27B 1.0.
Compares ukisai's Swift 1.5 NVFP4 and RadixArk's Qwen 3.8 27B NVFP4 via 10 tests on an RTX PRO 6000 using SGLang, covering speed, tool calling, 262K context, games, SVG, video editing, voxels, motion
Demonstrates running Qwen3.6-35B-A3B in oMLX 0.7.1.dev1 on Apple M5 Max MacBook Pro with 128GB unified memory, achieving 220 TPS via chat, .NET migration, and SVG image creation tasks.
Locally installed and tested Qwen-Image-2.1-Turbo, an accelerated checkpoint of Qwen-Image-2.1 for text-to-image generation and image editing using 8 denoising steps.
Locally installs and tests Iris 3B, a model that paints every pixel directly.
Covers Claude Haiku 5.5, GPT-6, GPT-6.1 Sol Ultrafast, Mistral Large 4, Reflection Beam, Grok updates, Gemini Agent, Meta Muse gadgets, and other AI news items.
Demonstrates enterprise adoption using multiple agents, workflow-based LLM calls, policy nodes versus RAG, and human approval within Oracle AI Agent Studio.
Evaluates Nex N2.5 mini using Performance, Memory, Reasoning, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender, and Godot tests.