Meta Muse Glimmer 30B tested - 16GB Local LLM setup
Muse Glimmer 30B performance, memory, agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot are tested on a single GPU.
Videos
Find videos about LLM models, hardware, runtimes, benchmarks and practical AI workflows.
Muse Glimmer 30B performance, memory, agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot are tested on a single GPU.
Sets up LangChain with OpenRouter, explaining tokens, temperature, and invoking Ling 3.0 Tiny via notebooks while handling rate limits and metadata inspection.
Analyzes Frontier Security's report on Kimi K3 exploiting a leaky sandbox allowlist to clone the benchmark repo and read answers, discussing implications for benchmark integrity and local model safety
Installs and tests Muse Glimmer in GGUF format using speculative decoding.
Programming test of Meta's Muse Glimmer 30B model on RTX 3090 Ti using Q4_K_XL and Q4 KV cache quantization, reporting 60 tok/s decode speed and 75% MTP accept rate.
Installs and tests Muse Glimmer, a 30-billion-parameter causal language model with a dedicated perception encoder, distilled from Muse Spark.
Compares Muse Glimmer 30B and Qwen3.6-27B in an agentic coding session using Pi Coding Agent, evaluating actual tool calls, tokens and results.
Tests Meta Muse Glimmer on browser workflows, C++ coding, FPS development, 3D CAD modeling, frontend design, creative writing, multimodal coding, and simulations.
Demonstrates using Qwen 3.6 27B Q6_K to reduce technical debt in ExtPackager and ImageViewer by fixing code problems while verifying no existing functionality breaks.
Compares Colibrì and llama.cpp running DeepSeek-V4-Flash-0731 on Ryzen 5 5600X with 61 GB RAM, detailing manual measurements since llama-bench lacks --no-repack support.
Tests Grug 35B QAT Q4 against Qwen 35B A3B Q4 using Performance, Memory, Agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender, and Godot benchmarks on a 16GB local system.
Demonstrates TestSprite Copilot driving end-to-end workflows with 40+ tools, Organization Collaboration, integrations with Linear, Figma & GitHub, Memory, and granular control with version history.
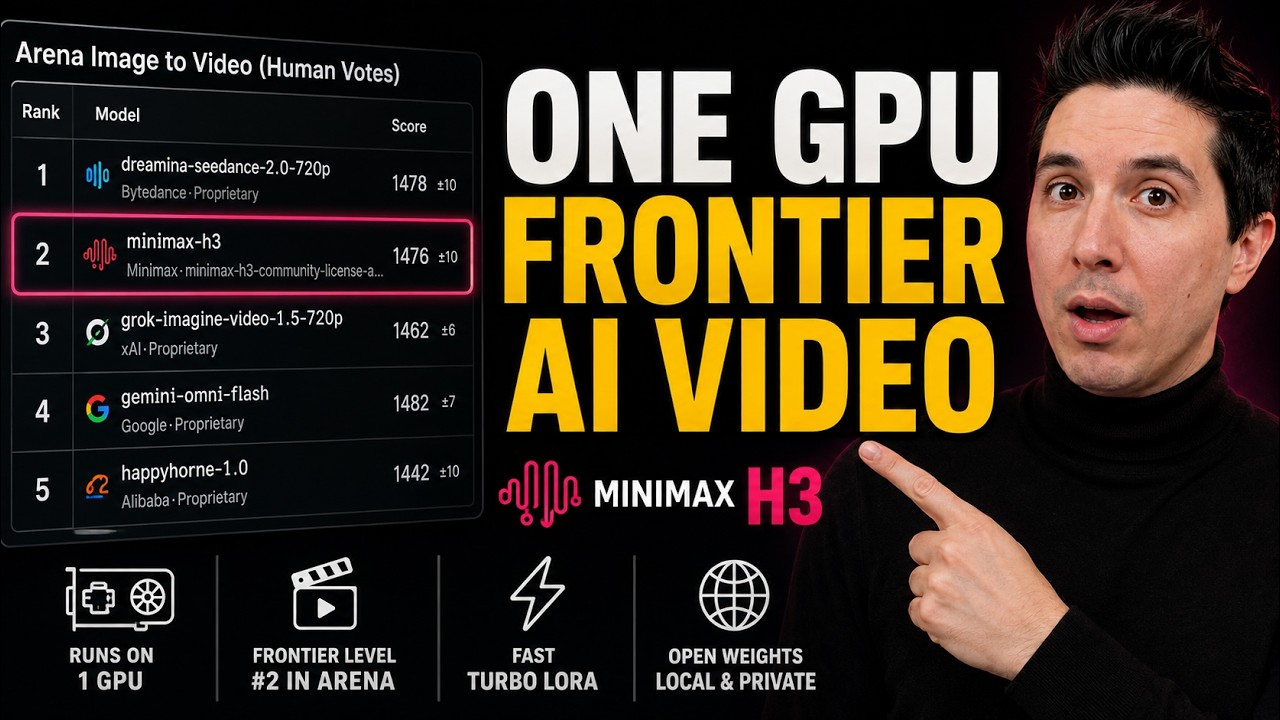
Runs MiniMax H3 locally in ComfyUI on an H100 to generate 5-second videos with native stereo audio, then swaps the 32B text encoder for a 4B one using ClipProj to reduce VRAM usage.
Installs and tests Neutrino-8B, storing every transformer linear five-valued in a single 2.56 GB container via sub-2 bits per weight quantization.
Covers semantic, episodic and procedural memory types within agentic AI engineering, positioning memory between context and harness engineering while highlighting retrieval quality impacts.
Installs and tests Maple-Prview, a 20B ternary model fitting in 6GB, demonstrating minimal performance gain from GPU usage.
Covers updates on SymphonyGen, MAC, Wan Animate 2, VocalRender, Hunyuan3D Buffalo, LeapTalk, Qwen 3.8 Max, WeatherNext 2, GPT math breakthroughs, ClinFusion, Gen1 welding, UBTECH swarm intelligence, X
Tests MiniMax H3 with SGLang-Diffusion and Turbo LoRA on RTX PRO 6000 Blackwell for t2v, i2v, Ref2VA, and stereo audio, examining Arena rankings and licenses.
Linking two DGX Sparks via high-speed cable pools their memory into approximately 220 GB unified VRAM, enabling local execution of quantized Kimi K3 and GLM models.
Tests Ling 3.0 Tiny on browser workflows, C++, Python, scene generation, 3D printer simulation, roleplay, creative writing, games, CAD modeling, and frontend design.
Installs and explains Prime Agent using Ollama and LM Studio, demonstrating an agent architecture capable of spawning its own agents via the PrimeIntellect-ai repository.
Alibaba releases Qwen robot foundation models RobotNav, RobotManip and RobotWorld for controlling robots with zero training.
Covers Seedance 2.5, FLUX 3 Video, Qwen3.8-Max, Meta Muse Code Beta, cybersecurity incidents involving Meta, OpenAI, Anthropic, Hank Green AI usage, Google AI updates, Jeff Dean's Discovery Loop, GPT-
Demonstrates maintaining an AI second brain using the second-brain-audit skill from coleam00/skills to ensure stored facts remain true, distinguishing between state and events.
Demonstrates the Gauntlet Loop multi-agent pattern where a Lead Agent delegates to Designer, Tester, and UI sub-agents while a Judge Agent evaluates results against an external benchmark until passing
Tests 1-bit Bonsai 27B performance, memory, agency, OpenAI Human Eval, Kanban, Sand Physics, and Dungeon Crawler against ~90% FP16 intelligence retention claim.
Explains graph engineering using LangGraph, Google ADK and AutoGen, positioning it against prompt, context, harness and loop techniques while distinguishing nodes and addressing applicability costs.
Installs and tests Qwen3.6-27B-Fable-Fusion-711-NM-DAU-NEO-MAX-MTP-GGUF locally, an open source multi-stage model fine tune for consumer hardware.
Tests Ling-3.0-tiny for token efficiency and production-scale agentic inference capabilities.
Running DeepSeek V4 Flash locally on two NVIDIA DGX Spark units while developing BridgeMind One and updating BridgeBench using Claude Opus 5, Fable 5, GPT 5.6 SOL, Kimi K3, Claude Code, and Codex.
Tests Meta Muse Code and Muse Spark 1.2 on browser workflows, C++ games, multimodal CAD, frontend dev, 3D modeling, flight sims, cinematic games, and FPS development.
Locally installs and tests Audio8 TTS Preview, a 0.6B multilingual text-to-speech model featuring zero-shot voice cloning capabilities.
Tests Muse Spark 1.2 and Muse Code via World of AI Bench, real-world coding, WebGL, and agentic software engineering, comparing performance against GPT-5.6 Luna, GPT-5.5, Claude Opus 4.8, and Grok 4.5
Evaluates Boris Cherny's advice to delete CLAUDE.md, skills, and hooks using benchmarks on Archon, comparing results against Anthropic's reduction of Claude Code's system prompt for Opus 5.
Evaluates Inkling-Small MLX Q9 using Inferencer App on M3 Ultra 512 GiB hardware, highlighting its status as a benchmark-topping open weight model with multimodal inference capabilities.
Installs and tests Muse Code by Meta, a terminal coding agent designed to handle complete software engineering tasks.
Evaluates Grug 27B QAT Q4 against Qwen 27B Q4 via Performance, Memory, Agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot tests on a 16GB system.
Explains loop engineering using ReAct agents, contrasting it with prompt, context, and harness engineering, covering second-model evaluators, self-prompting, and shared memory outside agent state.
Compares KAT-Coder-V2.5-Dev and Qwen3.6-35B-A3B within Pi Coding Agent on a .NET repo for codebase analysis and prioritized feature roadmaps.
Installs and tests Shieldstral from Mistral, a compact 3B-parameter, policy-adaptive multimodal safety classifier.
Regina test set results compare Gemma 26B and Qwen 35B using IQ4 quants from unsloth, identical sampling parameters, prompts, harness, and llama-server versions on Nvidia GPUs.
Installation guide for running MiniMax H3 in ComfyUI, covering text-to-video, image-to-video, reference-to-video, video editing, audio reference, performance optimization, low VRAM usage, and LoRA tra
Demonstrates connecting Higgsfield MCP server to Claude Code for an end-to-end cinematic workflow using MiniMax-H3, Seedance 2.0, Kling 3.0, Grok Imagine 1.5, Google/Gemini Omni Flash, Veo 3.1 and Ali
Locally installs and tests Nemotron-3-Embed-1B, a text embedding model optimized for retrieval and semantic similarity tasks.
Qwen 3.6 35B A3B and Gemma 4 26B A4B are tested on updating documentation and verifying tests for mature legacy code using the swing-extras project.
Tests Traycer multi-agent collaboration using Claude Fable 5 and local Qwen 27B on a coding task, comparing results against Qwen 27B solo performance.
Tests Qwen 3.8 Max in coding, frontend, Three.js, agents, research, and visual reasoning versus Claude Opus 5, GPT-5.6 Sol, and Gemini. Covers Qwen 3.8 27B open-weight release.
Compares three open stalwart models: Qwen 3.8 Max, DeepSeek V4 Flash, and Kimi K3 through tests evaluating their performance capabilities.
Tests Qwen 3.8-Max vision capabilities.
Speed test of DeepSeek-V4-Flash-0731-MLX using Inferencer App v2.2.3 and DSpark on Mac Studio M3 Ultra 512 GiB.