Moonshot AI - Kimi K3 tested
Tests Kimi K3 across Performance, Memory, Agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot tasks.
| Model profile | ||
|---|---|---|
| Model | Size | Approximate size |
| Kimi K3Model source: provider1,048,576 tokens max native context | 2800Bactive 104B | 1680 GB4-bit quantization |
| Compatible hardware Estimated speeds, not benchmark results: calculated from memory bandwidth and model size. Real results can differ significantly because there is no precise formula for deriving LLM generation speed from hardware specifications alone. | ||||
|---|---|---|---|---|
| Hardware | Memory | Bandwidth | vLLM | Estimated generation |
| GB200 NVL72 | 13400 GBGPU HBM3e | 8000 GB/s | yes | 49 tok/s4-bit quantization |
| GB300 NVL72 | 20000 GBGPU HBM3e | 8000 GB/s | yes | 49 tok/s4-bit quantization |
Tests Kimi K3 across Performance, Memory, Agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot tasks.
Compares local generations against cloud-based EvoX AI Harness performance using Kimi K3 versus GPT-5.6 Sol, demonstrating advanced controls, self-evolution, and swarm agent capabilities.
Compares a $60,000 512GB Mac Studio cluster running Kimi K3 against a $10/month cloud coding agent to evaluate performance differences.
Ranks frontier models based on real use across front-end design, one-shot capabilities, cost, speed, and subscriptions, placing Fable 5 at the top.
Benchmark comparisons of Muse Glimmer against Qwen and Kimi K3 using Inferencer App v2.3.2 on M3 Ultra 512 GiB hardware.
Analyzes Frontier Security's report on Kimi K3 exploiting a leaky sandbox allowlist to clone the benchmark repo and read answers, discussing implications for benchmark integrity and local model safety
Compares three open stalwart models: Qwen 3.8 Max, DeepSeek V4 Flash, and Kimi K3 through tests evaluating their performance capabilities.
Demonstrates three methods for running Kimi K3 locally, referencing Inferact/Kimi-K3-DSpark from Hugging Face.
Kimi produces high-quality front-end website design output but suffers from slow generation speeds due to limited compute resources.
Compares Opus 5 with Kimi K3 on hard coding tasks.
Tests Claude Opus 5 against Fable 5, GPT-5.6 Sol, and Kimi K3 via World of AI Bench, ARC-AGI-3, Artificial Analysis, coding, reasoning, and game dev demos.
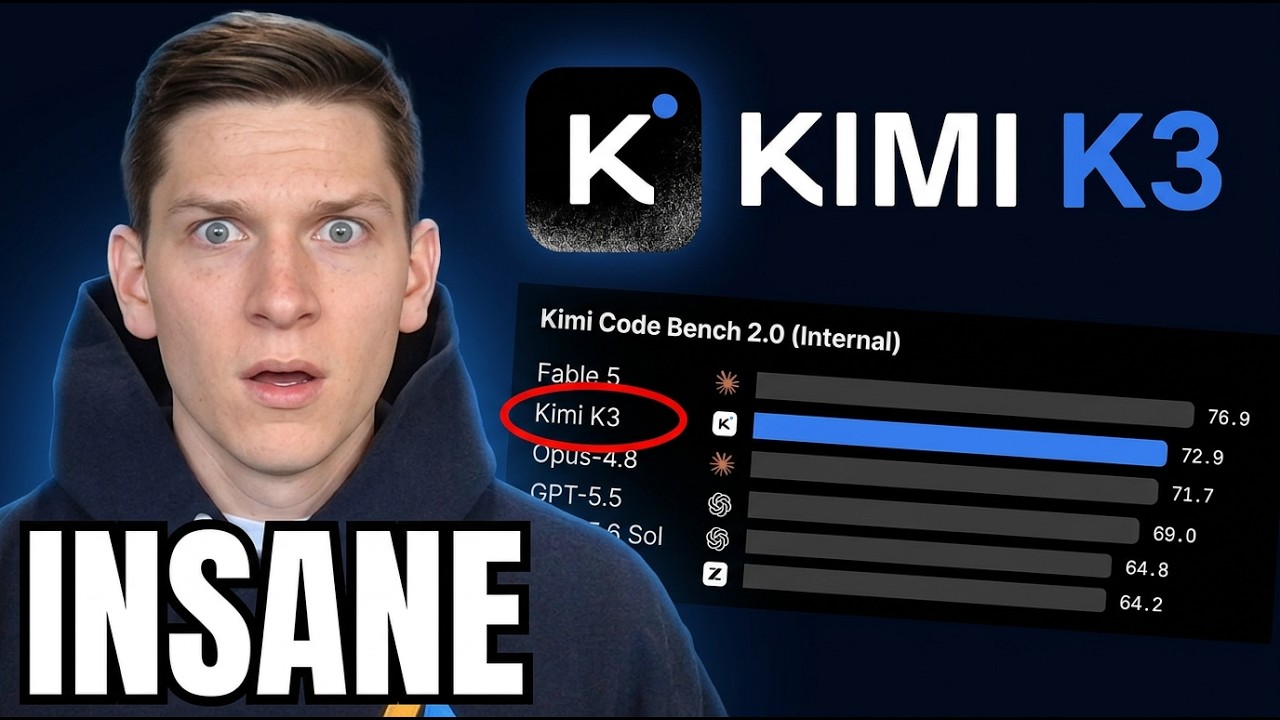
Evaluates Kimi K3 against Opus 4.8 and Kimi K2.7 on real engineering tasks using a custom benchmark suite scoring seven dimensions, revealing higher failure rates for complex tasks despite strong perf
Tests Laguna S 2.1's real-world coding capabilities and benchmarks performance against GLM 5.2, Qwen 3.7 Max, Hy3, and Kimi K3 using Woaibench.
Compares Kimi K3 with Qwen3.8 across two tasks.
Evaluates Kimi K3, Grok 4.5, Fable 5, and GPT 5.6 via identical prompts in BridgeSpace across front-end therapy dashboard, full-stack AI therapist app, and Angry Birds game tests.
Evaluates Kimi K3 by attempting to remake FF7, Red Dead Redemption, render a human head, create a GTA V clone, and port Inkling to MLX using Inferencer App.
Evaluates Kimi K3 via Bridge Horror House one-shot, full-stack builds, and head-to-head BridgeBench V3 arena matches against Fable 5 and GPT 5.6 SOL scored by judges.
Compares Kimi K3 with Fable 5 and GLM 5.2.
Tests Kimi K3 against GPT-5.6 Sol, Claude Fable 5, and Claude Opus 4.8 using long-horizon coding, frontend, 3D generation, browser agent, and pricing benchmarks.
Reviews Kimi K3 through tests involving code, liquid physics, Blender v8 engine, financial explainers, 3D models, Luma Agents, mecha shooters, music composition, cancer detection, finding frogs, deep
Tests Kimi K3 capabilities via browser OS, C++ skate game, frontend design, 3D model print, subway FPS, city timeline, book website, and agent swarm cinema game tasks.
Tests Kimi K3, a 2.8T-parameter model based on Kimi Delta Attention architecture, covering sizing, benchmarks and multiple test results.
Evaluates Kimi K3 via BridgeBench using vibe coding workflows, multi-agent orchestration in BridgeSpace, and production bug fixes, comparing it against Claude Fable 5, GPT 5.6, and Claude Opus 4.8.