Kimi K3 vs Fable 5 vs GPT 5.6 vs Grok 4.5
Evaluates Kimi K3, Grok 4.5, Fable 5, and GPT 5.6 via identical prompts in BridgeSpace across front-end therapy dashboard, full-stack AI therapist app, and Angry Birds game tests.
| Model profile | ||
|---|---|---|
| Model | Size | Approximate size |
| Grok 4.5Model source: provider500,000 tokens max native context | not available | not available4-bit quantization |
Evaluates Kimi K3, Grok 4.5, Fable 5, and GPT 5.6 via identical prompts in BridgeSpace across front-end therapy dashboard, full-stack AI therapist app, and Angry Birds game tests.
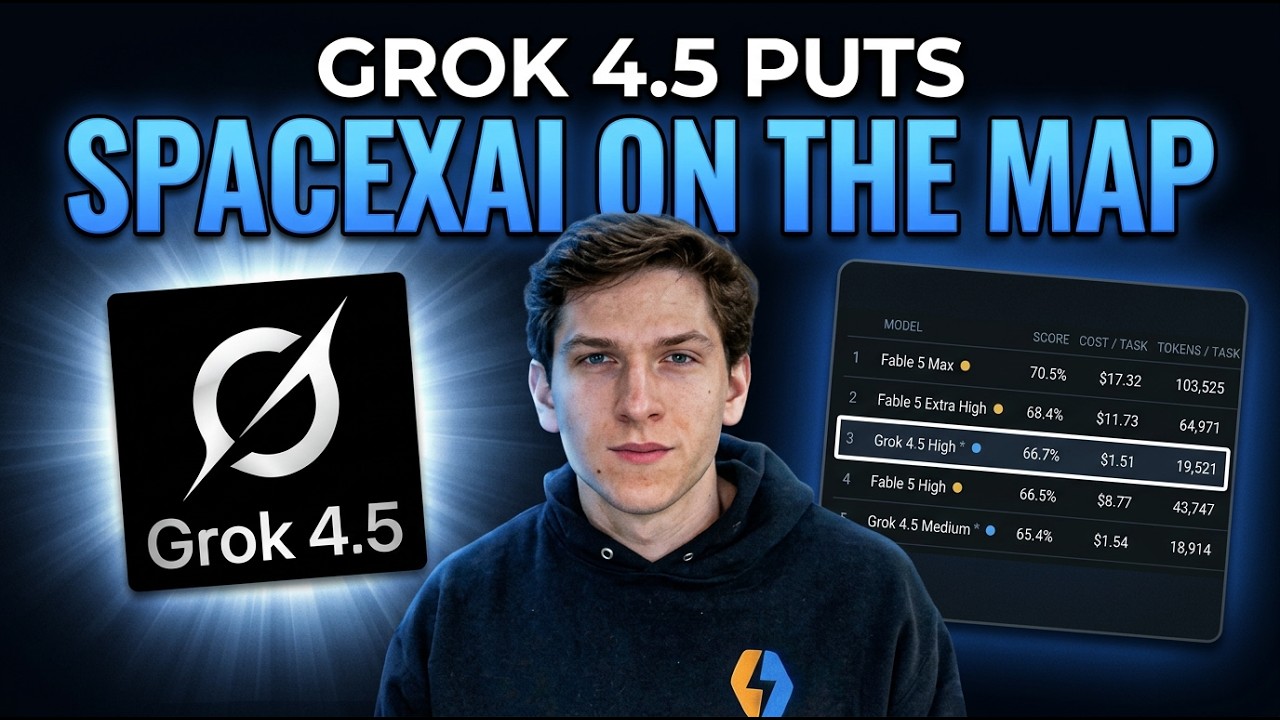
Evaluates Grok 4.5 via Artificial Analysis coding index, building apps, and comparing against Fable 5 and GPT 5.5, noting CursorBench leakage.
Tests Grok 4.5 via Terminal Bench, SWE Bench Pro, and real-world coding tasks, comparing performance, pricing, speed, and token efficiency against Claude Fable 5, GPT-5.5, Claude Opus 4.8, and Gemini
Tests Grok 4.5 against GPT and Claude Opus via browser OS, skydiving simulation, sprite sheet games, Linux drivers, frontend design, C++ skate games, 3D modeling, and Subway FPS tasks.
Evaluates Grok 4.5 via BridgeBench agentic coding workflows, comparing performance against Claude Opus 4.7, GPT 5.5, and Fable 5 using live leaderboard scores.