
Video
Alex Ziskind
2026-08-01
DGX Station running GLM5.2 in VSCode
Demonstrates a single-user DGX Station setup with 748GB of unified memory running GLM 5.2 in VSCode.
| Model profile | ||
|---|---|---|
| Model | Size | Approximate size |
| GLM 5.2Model source: provider1,048,576 tokens max native context | 744Bactive 40B | 446.4 GB4-bit quantization |
| Compatible hardware Estimated speeds, not benchmark results: calculated from memory bandwidth and model size. Real results can differ significantly because there is no precise formula for deriving LLM generation speed from hardware specifications alone. | ||||
|---|---|---|---|---|
| Hardware | Memory | Bandwidth | vLLM | Estimated generation |
| DGX H200 | 1128 GBGPU HBM3e | 4800 GB/s | yes | 74 tok/s4-bit quantization |
| DGX Station | 748 GBCoherent Memory | 7100 GB/s | yes | 104 tok/s4-bit quantization |
| ET900N G3 | 748 GBCoherent Memory | 7100 GB/s | yes | 104 tok/s4-bit quantization |
| DGX B200 | 1440 GBGPU HBM3e | 8000 GB/s | yes | 115 tok/s4-bit quantization |
| GB200 NVL72 | 13400 GBGPU HBM3e | 8000 GB/s | yes | 115 tok/s4-bit quantization |
| GB300 NVL72 | 20000 GBGPU HBM3e | 8000 GB/s | yes | 115 tok/s4-bit quantization |
Demonstrates a single-user DGX Station setup with 748GB of unified memory running GLM 5.2 in VSCode.

Tests how many AI agents the ASUS ExpertCenter Pro ET900N G3 can run using its 748GB unified memory, 400Gb networking, and 1400 watt superchip.

Remakes GTA using Fable 5, Opus 5, GPT-5.6 Sol, and GLM 5.2 in a coding showdown comparing cloud giants against the open-weight champion.

Evaluates Inferencer Labs' Macaron-V1 LoRA for GLM-5.2 on an M3 Ultra 512GB using music generation, human anatomy, game development tasks and photorealistic face creation tests.
Tests Laguna S 2.1's real-world coding capabilities and benchmarks performance against GLM 5.2, Qwen 3.7 Max, Hy3, and Kimi K3 using Woaibench.

Installs Colibri to shrink the full GLM 5.2 locally without GPU.

Compares Kimi K3 with Fable 5 and GLM 5.2.

Installs Colibri and runs full GLM 5.2 locally without GPU using JustVugg/colibri.
Demonstrates building a Chrome extension using the GLM 5.2 model, detailing installation via Developer Mode and loading unpacked files.
Compares local GLM 5.2 on M3 Ultra 512GB via Inferencer App against cloud Claude Sonnet 5 and Opus 4.8 using CometAPI in Chat, Terminal, and AI Agent OpenCode modes for speed and capability.
Tests Z.ai's GLM-5.2 via hosted web app, API, agent harness, and self-hosted setups using webpage building, Cursor integration, Remotion animations, and Inference.net traffic mirroring.

Compares GLM-5.2 and Claude Opus 4.8 via skydiving simulation, Windows XP-style AI app, 3D model generation, and time travel scene tests evaluating reasoning, coding, creativity, and consistency.

Tests the speed impact of Multi-Token Prediction on GLM 5.2 using Inferencer App v2.0.6 on an M3 Ultra 512GB system.
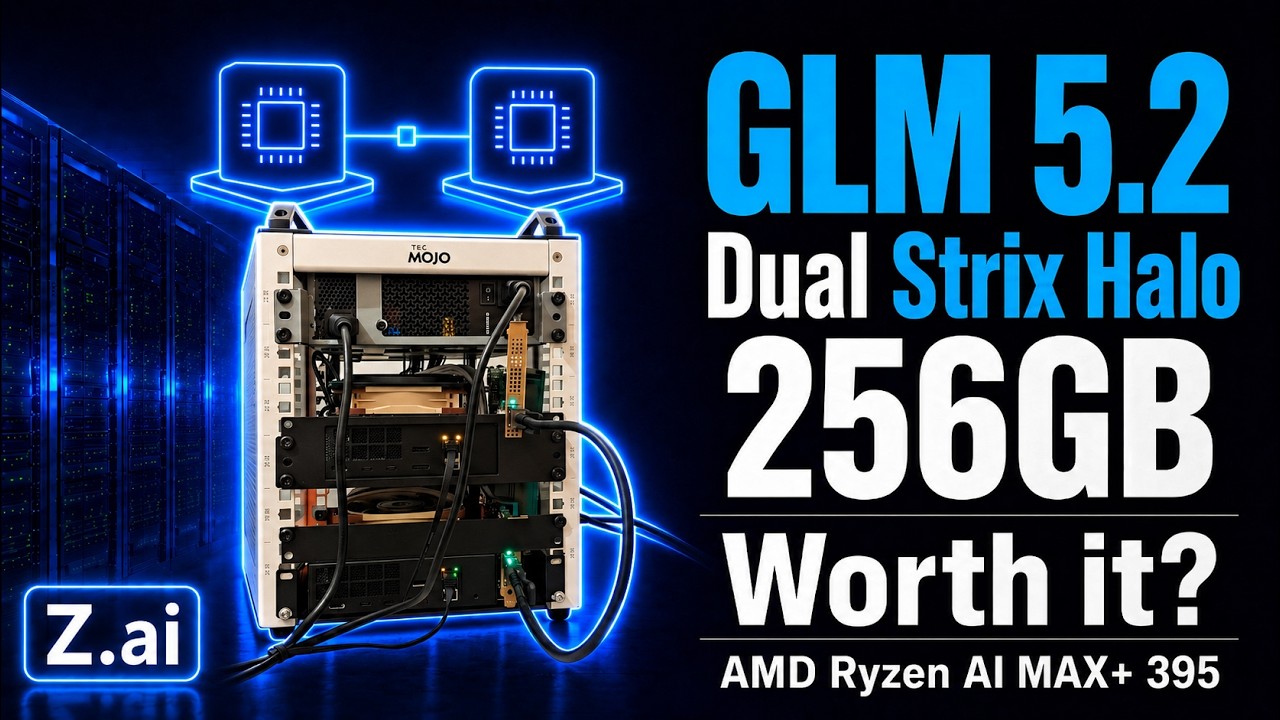
Evaluates GLM 5.2 on dual Strix Halo via UD-IQ2_M quantization, measuring token generation/prompt processing speeds against DeepSeek V4 Flash and testing coding capability with SWE Bench verified mini

GLM 5.2, Qwen 3.7, and MiniMax m3 are compared on real coding tasks performed live within the Hermes Agent environment.
Tests Z.AI GLM-5.2 in Claude Code UltraCode Mode against Claude Opus, GPT-5.5, and frontier-model workflows for real technical planning and implementation work.

Compares local models GLM 5.2 and Kimi K2.7 Code against cloud options Gemini Pro, Claude Sonnet, and Claude Fable using Inferencer App on Mac Studio M3 Ultra 512GB across game development tasks.

Evaluates why the open-source community favors GLM-5.2, identifies its shortcomings, and specifies the hardware required for local execution.

Tests GLM 5.2 and Kimi 2.7 Coder using Ollama Cloud and Pi agent on sorting algorithm visualizers and Rust desktop file apps via running and debugging.

Tests GLM-5.2 against GPT-5.5, Claude Opus 4.8, and Gemini 3.1 Pro using Design Arena, DeepSWE, Frontier SWE, Terminal-Bench, and SWE-bench Pro for coding, agentic workflows, and frontend tasks.

GLM-5.2 and Claude Opus 4.8 are compared on real coding tasks within the Hermes Agent environment across multiple tests.

Evaluates GLM 5.2 performance using Inferencer App on M3 Ultra 512GB across photorealism, sound generation, 3D game dev, coding, maths, logic tests and AI safety.
Evaluates GLM 5.2 using Ollama Cloud and the Pi agent on three coding tests: a sorting algorithm, six algorithms with visualization, and a Hantavirus simulation in Rust, checking first-time compilatio
Reviews GLM 5.2 capabilities including digital earth, animation, 3D models, ray tracing, music composition, math animation, deep research and specs.

Compares GLM-5.2 and Kimi K2.7 on real coding tasks within the Hermes Agent environment through a live demonstration.

Hands-on testing of GLM-5.2 from Z.AI covers architecture analysis and execution of two coding tasks.
Tests GLM-5.2 on browser OS, C++ games, subway scenes, frontend design, 3D printer simulation, CAD, MotoGP games, and drum kits via practical coding, simulation, and design tasks.

Evaluates GLM-5.2 via video editing, Splunk Cyber CTF challenge, and Mario Clone game creation, comparing results against MiniMax M3.