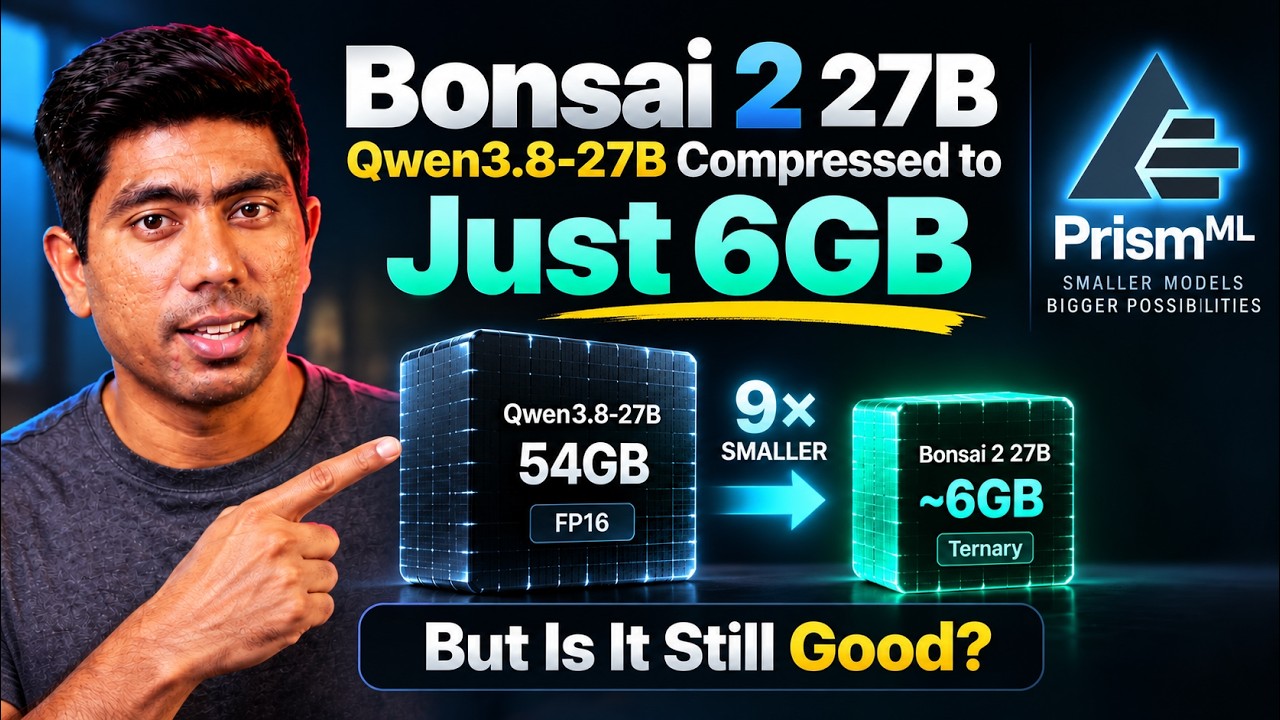
Bonsai 2 27B: Qwen3.8-27B Compressed to Just 6GB — But Is It Still Good?
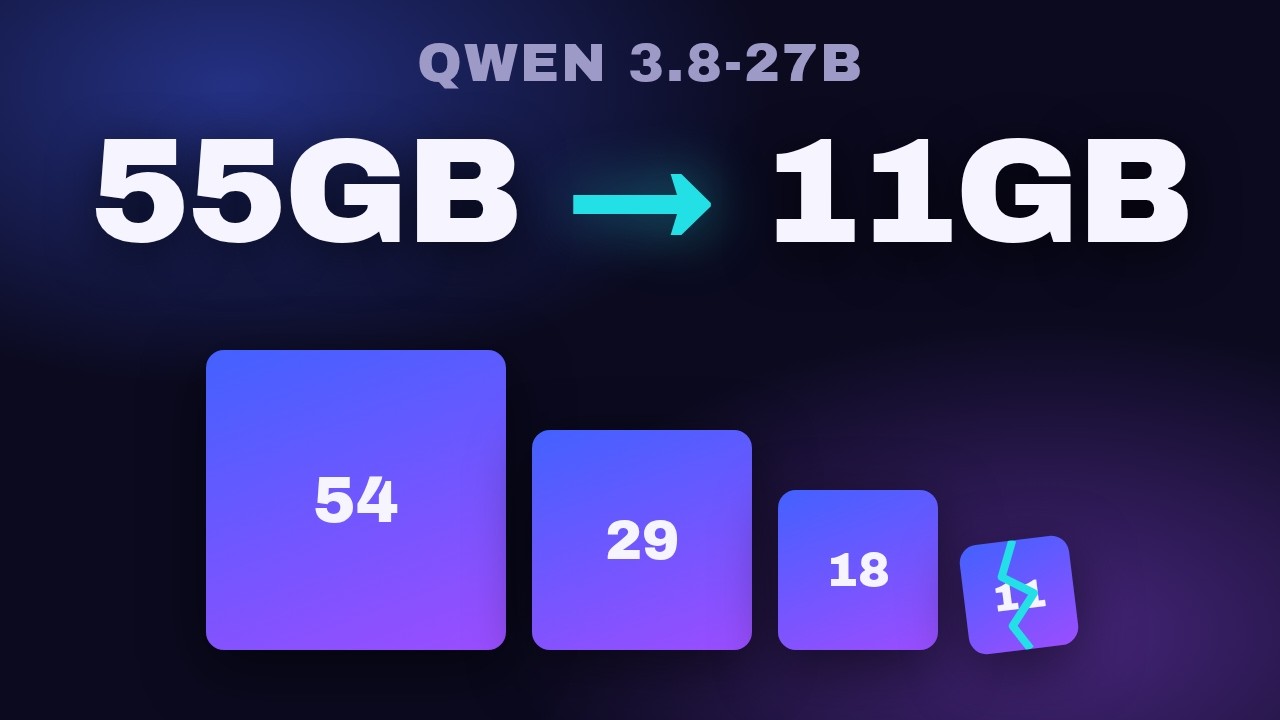
Bonsai 2 27B compresses Qwen3.8-27B from ~54 GB FP16 to ~6 GB using ternary weights, retaining ~98.2% of aggregate benchmark performance per PrismML.
| Model profile | ||
|---|---|---|
| Model | Size | Approximate size |
| Qwen 3.8 27BModel source: provider262,144 tokens max native context | 27B | 16.2 GB4-bit quantization |
| Compatible hardware Estimated speeds, not benchmark results: calculated from memory bandwidth and model size. Real results can differ significantly because there is no precise formula for deriving LLM generation speed from hardware specifications alone. | ||||
|---|---|---|---|---|
| Hardware | Memory | Bandwidth | vLLM | Estimated generation |
| DDR5 32GB Computer | 32 GBRAM | 89.6 GB/s | no | 3 tok/s4-bit quantization |
| Mac mini M4 | 24 GBUnified RAM | 120 GB/s | no | 4 tok/s4-bit quantization |
| Radeon 8060S 96GB | 96 GBUnified RAM | 256 GB/s | yes | 8 tok/s4-bit quantization |
| M4 Pro | 24 GBUnified RAM | 273 GB/s | no | 9 tok/s4-bit quantization |
| DGX Spark | 128 GBUnified RAM | 273 GB/s | yes | 9 tok/s4-bit quantization |
| M5 Pro | 64 GBUnified RAM | 307 GB/s | no | 10 tok/s4-bit quantization |
| M5 Max | 128 GBUnified RAM | 614 GB/s | no | 20 tok/s4-bit quantization |
| M3 Ultra | 96 GBUnified RAM | 819 GB/s | no | 27 tok/s4-bit quantization |
| RTX 3090 Ti | 24 GBGPU VRAM | 1008 GB/s | yes | 33 tok/s4-bit quantization |
| M5 Ultra | 256 GBUnified RAM | 1200 GB/s | no | 39 tok/s4-bit quantization |
| RTX 5090 | 32 GBGPU VRAM | 1792 GB/s | yes | 58 tok/s4-bit quantization |
| RTX PRO 6000 | 96 GBGPU VRAM | 1792 GB/s | yes | 58 tok/s4-bit quantization |
| DGX H200 | 1128 GBGPU HBM3e | 4800 GB/s | yes | 145 tok/s4-bit quantization |
| DGX Station | 748 GBCoherent Memory | 7100 GB/s | yes | 204 tok/s4-bit quantization |
| ET900N G3 | 748 GBCoherent Memory | 7100 GB/s | yes | 204 tok/s4-bit quantization |
| DGX B200 | 1440 GBGPU HBM3e | 8000 GB/s | yes | 225 tok/s4-bit quantization |
| GB200 NVL72 | 13400 GBGPU HBM3e | 8000 GB/s | yes | 225 tok/s4-bit quantization |
| GB300 NVL72 | 20000 GBGPU HBM3e | 8000 GB/s | yes | 225 tok/s4-bit quantization |
Bonsai 2 27B compresses Qwen3.8-27B from ~54 GB FP16 to ~6 GB using ternary weights, retaining ~98.2% of aggregate benchmark performance per PrismML.
Compares Bonsai 2 against Qwen 3.5 9B, Qwen 3.6 35b-a3b and Bonsai 1 using Bob-Bench scores on 8GB VRAM configurations.
Installs and compares Swift-Qwen3.8-27B with Original Qwen to evaluate whether the claim of fewer thought tokens holds true.
Demonstrates combining vibe coding with rigorous specifications through iterative refinement passes before implementing the Dust to Dominion game using an LLM to generate 100% of the code.
Locally installs and tests Ternary-Bonsai-2-27B-gguf.
Tests Bonsai 2 27B across browser workflows, website generation, C++ game development, Blender scenes, FPS games, frontend design, image-to-SVG conversion, and simple 3D games.
Token generation speeds were measured for Gemma 4 E2B, Gemma 4 12B, gpt-oss 20B, Gemma 4 26B, Qwen 3.6 35B, and Qwen 3.8 27B using Ollama on a Geekom A9 Max mini PC with 32 GB RAM.
Compares local Qwen3.8-27B with cloud models for TestSprite AI testing efficiency during tool calls, test generation, result analysis and iteration.
Demonstrates LiteLLM Auto Router with Pi Coding Agent, Ollama, and oMLX on Apple Silicon, comparing heuristic versus LLM classifiers for Qwen3.5 4B, Gemma 4, and Qwen3.8 27B.
Runs Gemma4 E4B and Qwen 3.8 27B on ZimaBoard 2 using llamacpp, comparing performance with an added RTX 2000 GPU through Kanban, Sand Physics, and Dungeon Crawler demos.
Compares Oh My Pi with Pi and OpenCode through initial setup, configuration tweaks, built-in tools, custom system prompts, compaction methods, sub-agents, and design philosophy analysis.
Benchmark Qwen 3.8 27B Q4_K_M via llama.cpp on MacBook Pro M5 Max versus RTX 5090, analyzing memory usage, GGUF headers, KV cache behavior, and MTP drafting performance at 8K context.
Muse Glimmer is rematched against Qwen 3.8 27B using TalkWithMe, with Qwen’s reasoning level increased to high for comparison.
Demonstrates setting up DeepSeek Harness with local Qwen 3.8 27B via Ollama to autonomously build and deploy a portfolio site to Vercel using GPU-generated tokens.
Tests Dirk Qwen 3.8 27B GGUF from peculiar-ragdoll using Performance, Memory, Agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot benchmarks.
Benchmark IBM Granite 4.2, Qwen 3.8 27B, Gemma 4, and Ornith 1.5 on an RTX 5090, measuring KV cache cost, usable context, generation speed, coding, math, and tool calling via Python tests.
Runs Qwen3.8 27B locally using Superlinked Inference Engine (SIE) for efficient execution.
Benchmarking Ornith 1.5 9B and 35B, Qwen 3.8 27B, and Gemma 4 on an RTX 5090 using llama-server with 4-bit weights and FP16 KV cache via code-graded metrics.
Compares Qwen 3.8 Flash Next and Qwen 3.8 27B architectures, detailing MoE, sparse attention, gated residuals, 51B n-gram lookup tables, and RTX 5090 MTP measurements.
Demonstrates running Qwen 3.8 27B on consumer-grade computers using LM Studio to select compatible high-quality quantizations and manage downloads.
Hands-on guide demonstrating local fine-tuning of the Qwen3.8 27B model using custom datasets.
Evaluates Qwen 3.8-27B MTP depths 2, 3, 4 versus off using llama.cpp on GMKtec EVO-X2, measuring throughput and verifying output identity via hashes under greedy and sampled settings.
Compares Qwen 3.8, 3.6 and 3.5 using 397 generations on an RTX 5090, analyzing MTP layer activation, split vision encoder, post-training effects, Terminal-Bench scores and token speeds.
Tests Qwen 3.8 27B, Muse Glimmer 30B and Gemma 4 26B on an RTX 5090 using Ollama, evaluating consistency across 12 accounting questions run 10 times each.
Performs unsloth/Qwen3.8-27B-GGUF quantizations Q1-Q8 using HumanEval within Kanban, Blender and Godot environments.
5:15
Runs Qwen 3.8 27B on an RTX 4060 using unsloth IQ4_XS quant and Pi agent harness, comparing results against Claude Opus 4.6 in agentic coding tests.
Evaluates 45 llama.cpp configurations for Qwen 3.8 27B on an RTX 5090, analyzing speculative decoding, KV cache quantization, flash attention, and context window impacts on speed and VRAM usage.
19:16
Tests Qwen3.8-27B via NINFER on RTX 5090 with DeepSeek harness across ~300 iterations to build a 3D Acropolis scene in a single HTML/CSS/JS file.
Compares Ornith-1.5 35B-A3B MoE and Qwen3.8-27B dense models via SVG creation, website generation, Playwright MCP tool calls, and .NET code migration tests.
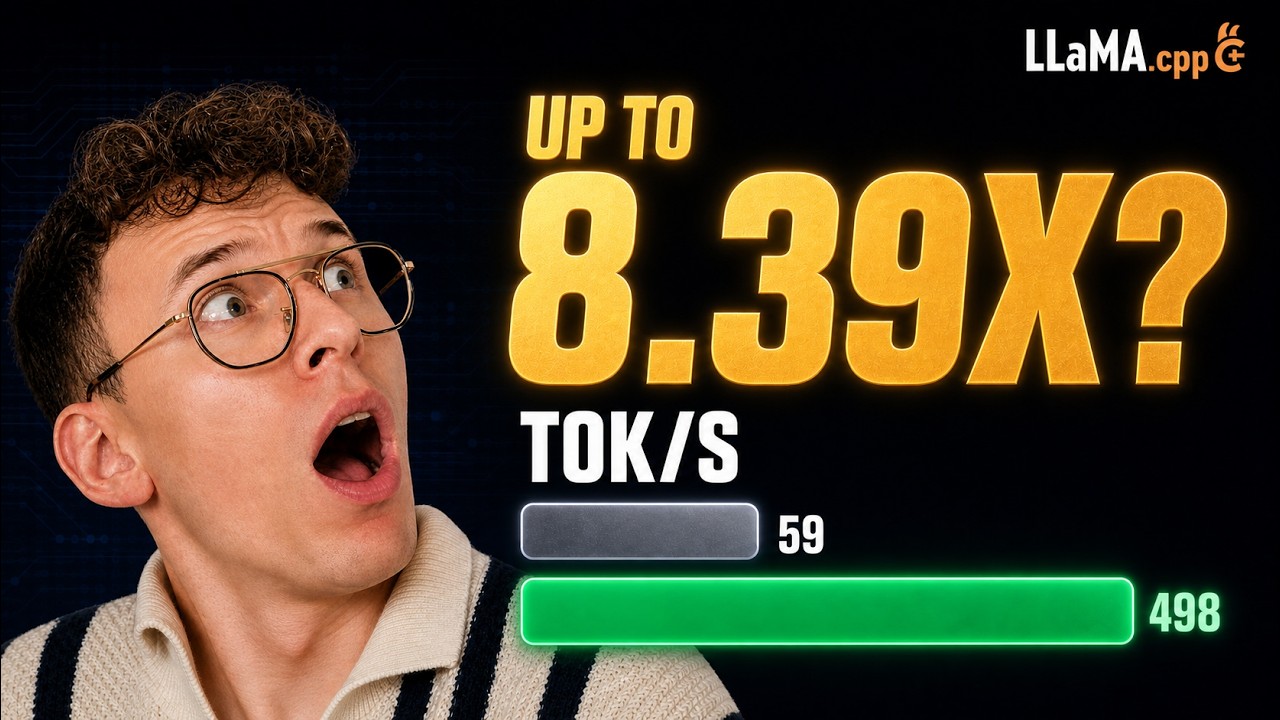
Benchmarks DFlash 2, n-gram, MTP and combinations for Qwen 3.8 27B in llama.cpp on RTX PRO 6000 Blackwell using LiveCodeBench and an 18-turn coding session.
Side-by-side coding test using Claude Code on Ollama to generate Space Invaders, Breakout, and Tetris HTML canvas games with Qwen 3.8 27B, Muse Glimmer, and Gemma 4 on an RTX 5090.
Demonstrates configuring an 8-bit quantized Qwen3.8-27B with DeepSeek Harness to edit its own code and enable inline image and video support via plugins.
Demonstrates building a local financial RAG using Qwen 3.8 27B, Ollama, Qdrant, LangChain and Chainlit on SEC 10-K filings with hybrid search, agentic filtering and streaming.
Muse Glimmer and Qwen 3.8 27B implement two new features in SuperAsteroids, scored by code review with merging or deleting branches based on results.
Tests experimental Apple Neural Engine Prefill for Qwen3.8-27B on Apple Silicon via oMLX, comparing performance with ANE enabled versus disabled during the prefill stage.
Evaluates optimal KV cache quantization using Bob-bench on Mac Studio and 4090 hardware across varying context lengths, referencing a Meta paper.
Installs DeepSeek Harness on Linux, wiring it to Ollama and Unsloth servers running Qwen 3.8-27B at 4-bit locally, then builds a to-do list app in 30 minutes at 16 tokens per second.
Installs and tests Escha-W2, a 2-bit quantized build of Qwen3.8-27B.
Tests Qwen 3.8 27B Q4_K_M reliability via clock tasks, Pomodoro timers, and building a Feed Aggregator in Nim using Ollama and Pi agent.
Tests Qwen3.8-27B local inference on Apple M5 Max, measuring TPS across reasoning levels and evaluating DFlash2 speculative decoding acceleration combined with varying thinking modes.
Tests how Qwen 3.8 27B reasoning levels impact output quality and token usage across tasks including stopwatch, typing speed, sand physics, dungeon crawler, notes app, blender windmill, and charts.
Tests Qwen 3.8 27B against Opus 4.6 on a live game development task using an existing codebase hosted at brrnout.com.
Evaluates Qwen 3.8-27B reasoning_effort levels via Tetris clone, volcano sim, spreadsheet, and drawing tests using identical official thinking samplers on a 17.9 GB 4-bit file.
Local installation and testing of Qwen3.8-27B using Dflash2, featuring live local benchmarking performance evaluations.
Demonstrates Qwen3.8-27B running unsupervised local coding tasks for 10 hours, including building a Pi/goal extension via Grok Build and optimizing SGLang-Omni to serve MiniMax-Music3.
Installs and tests hermes agent loop functionality using Qwen3.8 27B to demonstrate recurring execution of prompts or slash commands.
Compares Qwen3.8 27B and Qwen3.6 27B using Regina on Minesweeper, VMs, py2c calc, encryption and memcached, analyzing reasoning tokens, degeneracy and failures.
Evaluates Qwen 3.8-27B quantizations (BF16, Q8, Q4 Unsloth, Q4_K_M Ollama, Q2) via one-shot exams measuring speed and quality against a BF16 baseline.
Tests Qwen 3.8 using Inferencer App v2.3.3 on M3 Ultra 512 GiB across 2 million tokens, varying temperature, quantization levels, and thinking modes.
Evaluates Qwen 3.8 27B using an eight-stage development plan on improved hardware achieving 70–130 tokens per second, with code review included.