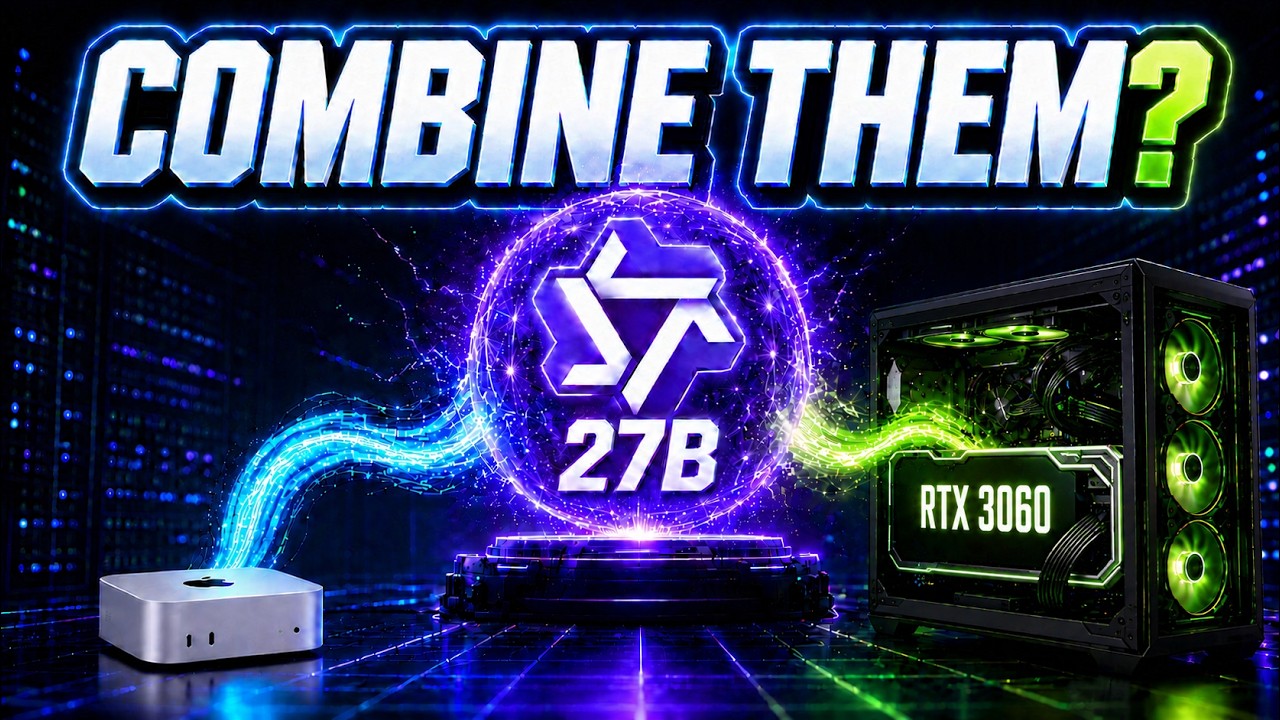
I Split Qwen 3.8 27B Model Across Mac and Nvidia PC (llama.cpp RPC Guide)
Evaluates Qwen3.8-27B inference via llama.cpp RPC across RTX 3060 and Apple Silicon Mac, comparing throughput metrics for single-card versus distributed layer loading.
| Model profile | ||
|---|---|---|
| Model | Size | Approximate size |
| Qwen 3.8 27BModel source: provider262,144 tokens max native context | 27B | 16.2 GB4-bit quantization |
| Compatible hardware Estimated speeds, not benchmark results: calculated from memory bandwidth and model size. Real results can differ significantly because there is no precise formula for deriving LLM generation speed from hardware specifications alone. | ||||
|---|---|---|---|---|
| Hardware | Memory | Bandwidth | vLLM | Estimated generation |
| DDR5 32GB Computer | 32 GBRAM | 89.6 GB/s | no | 3 tok/s4-bit quantization |
| Mac mini M4 | 24 GBUnified RAM | 120 GB/s | no | 4 tok/s4-bit quantization |
| Radeon 8060S 96GB | 96 GBUnified RAM | 256 GB/s | yes | 8 tok/s4-bit quantization |
| M4 Pro | 24 GBUnified RAM | 273 GB/s | no | 9 tok/s4-bit quantization |
| DGX Spark | 128 GBUnified RAM | 273 GB/s | yes | 9 tok/s4-bit quantization |
| M5 Pro | 64 GBUnified RAM | 307 GB/s | no | 10 tok/s4-bit quantization |
| M5 Max | 128 GBUnified RAM | 614 GB/s | no | 20 tok/s4-bit quantization |
| M3 Ultra | 96 GBUnified RAM | 819 GB/s | no | 27 tok/s4-bit quantization |
| RTX 3090 Ti | 24 GBGPU VRAM | 1008 GB/s | yes | 33 tok/s4-bit quantization |
| M5 Ultra | 256 GBUnified RAM | 1200 GB/s | no | 39 tok/s4-bit quantization |
| RTX 5090 | 32 GBGPU VRAM | 1792 GB/s | yes | 58 tok/s4-bit quantization |
| RTX PRO 6000 | 96 GBGPU VRAM | 1792 GB/s | yes | 58 tok/s4-bit quantization |
| DGX H200 | 1128 GBGPU HBM3e | 4800 GB/s | yes | 145 tok/s4-bit quantization |
| DGX Station | 748 GBCoherent Memory | 7100 GB/s | yes | 204 tok/s4-bit quantization |
| ET900N G3 | 748 GBCoherent Memory | 7100 GB/s | yes | 204 tok/s4-bit quantization |
| DGX B200 | 1440 GBGPU HBM3e | 8000 GB/s | yes | 225 tok/s4-bit quantization |
| GB200 NVL72 | 13400 GBGPU HBM3e | 8000 GB/s | yes | 225 tok/s4-bit quantization |
| GB300 NVL72 | 20000 GBGPU HBM3e | 8000 GB/s | yes | 225 tok/s4-bit quantization |
Evaluates Qwen3.8-27B inference via llama.cpp RPC across RTX 3060 and Apple Silicon Mac, comparing throughput metrics for single-card versus distributed layer loading.
Qwen 3.8-27B versus Qwen 3.6-35B-A3B at BF16 on a custom exam featuring Tetris, volcano physics, spreadsheets, and SVG tasks, plus Claude Opus 4.6 comparison.
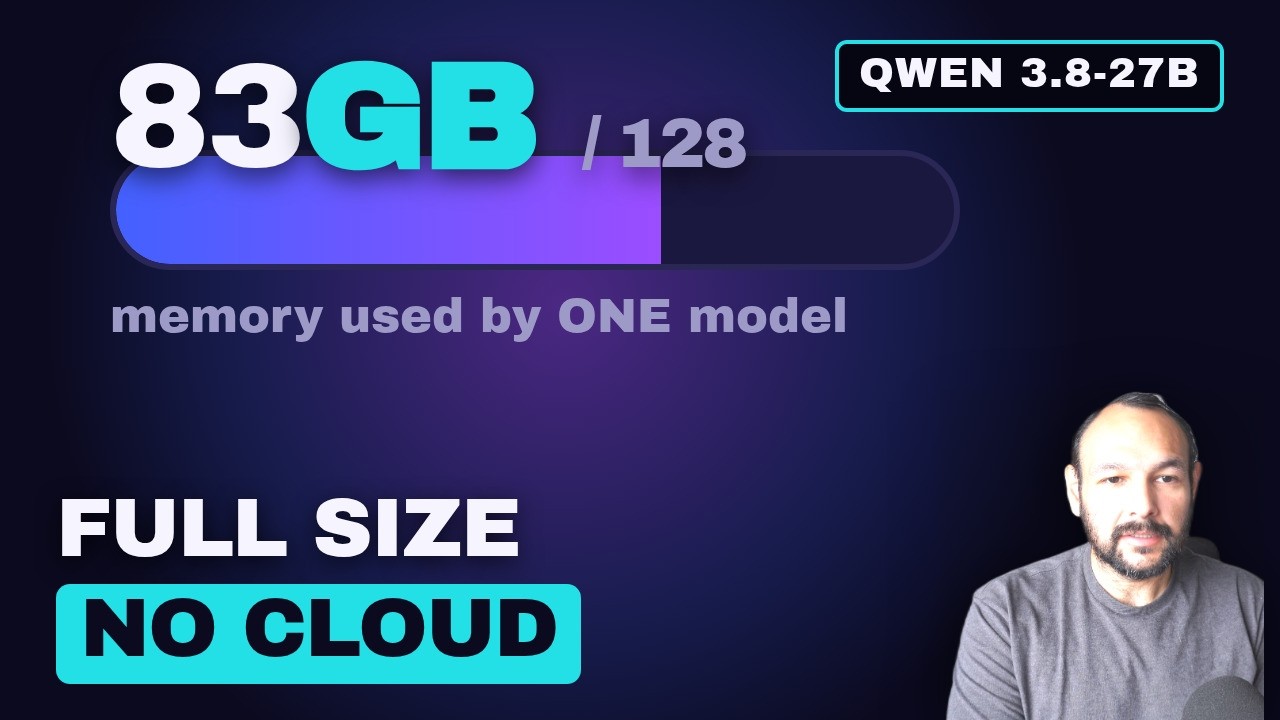
Demonstrates installing Unsloth Studio via terminal on AMD ROCm hardware, loading the full 55 GB Qwen 3.8-27B model consuming 83 GB RAM, and testing local chat, vision, and deep research capabilities.
Evaluates Qwen 3.8 27B against Qwen 3.6 27B on psim-blackbox using pi harness 0.79.3 across low, medium, and xhigh reasoning settings, showing performance varies significantly by mode.
Evaluates Qwen 3.8-27B, a native multimodal dense model reading images and video, covering Unsloth quants, thinking-effort controls, NVFP4 Blackwell builds, and benchmarks against Opus 4.6 Max.
Side-by-side coding test using Claude Code on Ollama to generate Space Invaders, Breakout, and Tetris HTML canvas games with Qwen 3.8 27B, Muse Glimmer, and Gemma 4 on an RTX 5090.
Tests Qwen3.8-27B via live tool calling with Playwright MCP Server and migrating a .NET solution from .NET 8 to .NET 10, while examining Preserve Thinking for multi-turn agentic work.
Tests unsloth/Qwen3.8-27B-GGUF performance, memory, agency, OpenAI Human Eval, Kanban, Sand Physics, Dungeon Crawler, Blender and Godot on a 16GB local setup using llama.cpp.
Evaluates Qwen 3.8 27B locally through code reviews of a nontrivial feature branch and analysis of technical documentation for gaps or outdated information.
Tests Qwen 3.8 27B, Nemotron 3.5 Lightning, and Muse Glimmer on an RTX 5090 using 16 hard math, coding, and reasoning problems via Ollama with Q4_K_M quantization, measuring accuracy, time, VRAM, and
Tests Qwen3.8-27B locally on RTX 4090 via Unsloth Dynamic 4-bit quant and Open WebUI against Claude Opus in coding, agentic tasks, vision and web dev.
Installs and tests Qwen3.8-27B Quant locally using llama.cpp, Ollama, and LM Studio.
Evaluates Qwen3.8-27B-MLX-Q9 performance using Inferencer App v2.3.2 on M3 Ultra 512 GiB across one million tokens.
Demonstrates setup of Qwen 3.8 27B bootstrapped by Qwen 3.6 27B on local infrastructure, where Qwen 3.8 27B programs Super Dario.
Tests Qwen3.8 27B across browser OS, C++ skate game, Subway FPS, 3D CAD, watch website, creative chat, multimodal coding, Chrono City timeline, Cinematic Steve’s PC repair, and Street Yeet game.
Locally evaluates Qwen3.8-27B against Qwen3.6-27B on coding, agents, tools, reasoning, hallucinations, speed, vision, Splunk CTF, and Mario clone creation.
Qwen3.8-27B runs locally on MacBook Pro M5 Max 128GB, evaluating speed, reasoning, coding, and offline performance via Pi coding agent and Mario game construction tasks.
Installs and tests Qwen3.8-27B locally.