$7 vs $0.65: Opus 5.5 and MiniMax M3.1 Flash on My Go Project
MiniMax M3.1 Flash and Claude Opus 5.5 were given three tasks from a 20,000-line Go project, passing every hidden check with costs of approximately $0.65 and $7 respectively.
| Model profile | ||
|---|---|---|
| Model | Size | Approximate size |
| Opus 5.5Model source: providernot available max native context | not available | not available4-bit quantization |
MiniMax M3.1 Flash and Claude Opus 5.5 were given three tasks from a 20,000-line Go project, passing every hidden check with costs of approximately $0.65 and $7 respectively.
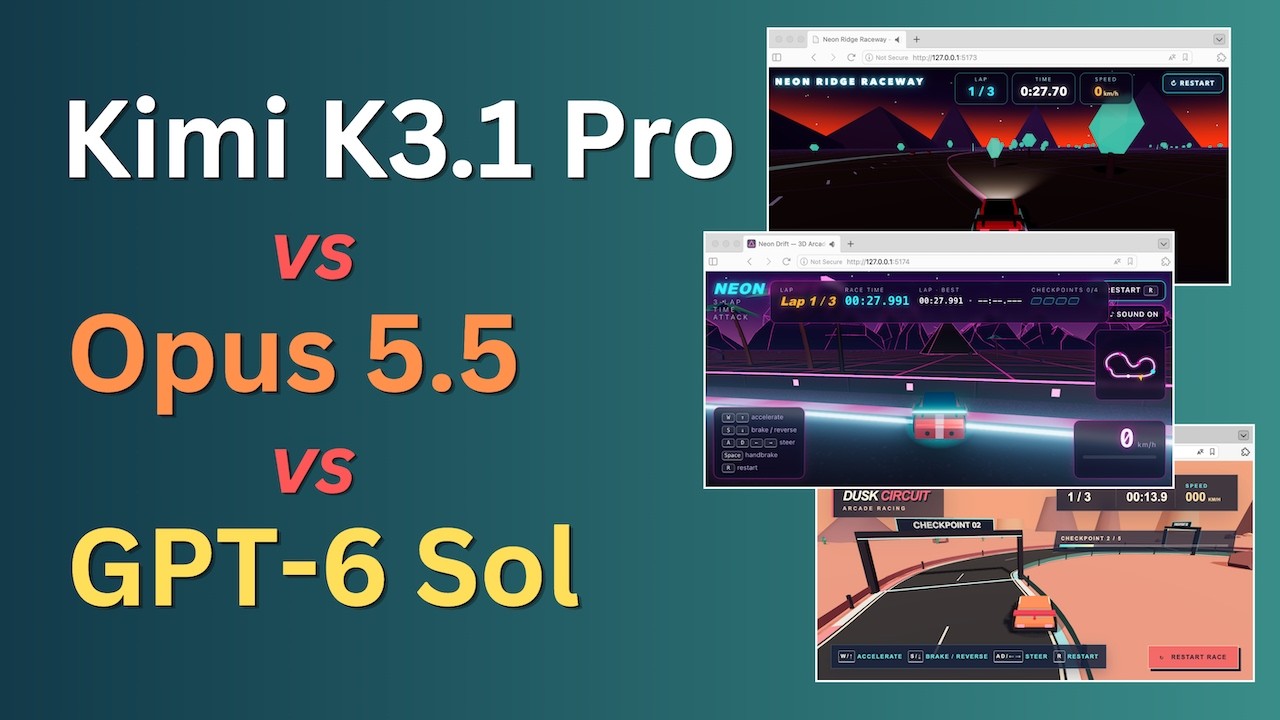
Kimi K3.1 Pro, Claude Opus 5.5 and GPT-6 Sol each have one hour to independently write code, run, debug and deliver a playable 3D racing game.
Compares qwen3.8:27B on MacBook Pro M5 Max versus Claude Opus across four coding and data tasks, measuring time, cost, tokens, and output quality using Ollama and Claude Code.
Compares DeepSeek V4.1 Flash and Claude Opus 5.5 solving an auto-updating links task in Texodus, noting costs of 6 cents versus $5.45 and observing DeepSeek’s search behavior during execution.
Enter Pro compares GPT-6 Astra, Opus 5.5 and local Qwen performance when building full web apps through side-by-side testing.
Demonstrates using Claude Opus 5.5 for game modding via pass-through mods, reverse engineering, rebuilding in Rust, and porting mechanics.
Demonstrates using Claude Opus 5.5 with Higgsfield MCP to autonomously generate the Texodus landing page and an 8-second promo video from minimal prompts.
Directly tests GPT-6 Sol and Claude Opus 5.5 against each other across three tasks instead of relying on companies' claims about their own models versus competitors' previous generations.
Demonstrates using local coding agent conversation files to improve rules via prompts or storing them in Databricks for querying with Claude Code and MCP.
Evaluates Claude Opus 5.5 via Recaptcha, ray tracing, live piano, math videos, Blender VR, Unreal games, music, FROG TEST, cancer ID, deep research, ideation, specs, guardrails.
Compares Claude Opus 5.5 and GPT-6 Sol performance simulating a latte.
Tests Claude Opus 5.5 via browser OS, C++, Blender, Godot, Subway FPS, and an original benchmark.
Benchmarks Claude Opus 5.5 via woaibench.ai across agentic coding, complex frontend development, visual design, games, and real-world tasks, evaluating performance, speed, and efficiency per task.