Mahjong solitaire built by Qwen 3.6 and Qwen 3.8 as agents
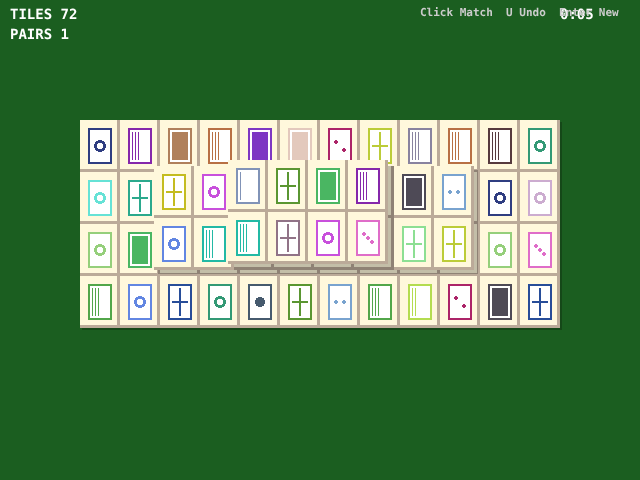
We asked Qwen 3.6 27B, Qwen 3.6 35B and Qwen 3.8 27B in NVFP4 to build Mahjong solitaire, played with the mouse, in SC# as an agent. 12 hidden tests checked the result. Qwen 3.6 27B in Thinking mode, Qwen 3.6 35B in Thinking mode and Qwen 3.8 27B in Think: medium each lost one hidden test, mostly because two different tile faces looked the same, and Qwen 3.6 35B in Instruct mode built no working game.
Author: Piotr SzawdyńskiPublished: 2026-10-15
Introduction
Can a local model build a tile game played with the mouse on its own, test it and submit working code? We gave Qwen 3.6 27B, Qwen 3.6 35B and Qwen 3.8 27B the same task: write Mahjong solitaire as an app in SC#, our C#-like scripting language, played with the mouse. Each model worked as an agent: it wrote the game, ran its own tests, fixed the code and submitted the game. Then 12 hidden tests checked whether the game follows the rules.
How a run works, how the task and the hidden tests are built and how we make sure the tests are fair is described in How we test local models that build apps as agents. This article covers only the results and the mistakes.
- Models: Qwen 3.6 27B; Qwen 3.6 35B, a mixture-of-experts model with about 3B active parameters; Qwen 3.8 27B, a newer version of the 27B model.
- Modes: Instruct mode and Thinking mode. Qwen 3.8 27B has thinking levels; we ran Think: medium.
- Quantization: NVFP4, a 4-bit format that needs about half the memory of FP8.
- Runtime: vLLM 0.30.0 with matching settings for all models.
Every setup ran the task once, and that run counts. We did not rerun failed runs. The aim is to show what a user can expect from one attempt, not the best possible result.
The task
The game is Mahjong solitaire with 72 tiles in 3 layers. The player clicks two free tiles with the same face to remove them. A tile is free when no tile lies on it and its left or its right side is open. U takes back the last removed pair, and the game shows how many pairs can still be removed. The game is won when all tiles are removed, and it shows NO MOVES when no pair is left to remove.
The exact rules the hidden tests check include the layout of the layers, which tile is under the mouse when tiles of several layers overlap (exactly at the edges of their rectangles), which tiles are free, how a click selects, moves the selection or removes a pair, the undo, the count of available pairs, the win and a new game with Enter. On the screen, the tests check that different faces look different and the same faces look the same, that the selected tile and a free tile under the mouse look different, and that a removed pair disappears from the screen. The model chooses how to build all of this.
Results
Three setups lost only one result, Qwen 3.6 27B in Instruct mode and Qwen 3.8 27B in Instruct mode lost two and three, and Qwen 3.6 35B in Instruct mode built no working game. The chart below shows the score of each setup: the share of passed results, the build of the game and the 12 hidden tests. One rule failed in four of the six setups: different tile faces must look different on the screen (see "Tiles that look the same").
Qwen 3.6 27B in NVFP4
Qwen 3.6 27B built a working game in both modes, with one lost hidden test in Thinking mode and two in Instruct mode. In both modes, two tile faces looked the same in the middle of the tile. In Instruct mode, a click on a tile that is not free also cleared the selection, although the task says that such a click changes nothing.
In Thinking mode, the model noticed on its own that its character tiles all looked the same, and it painted them again with different bars. It missed the same problem in two of its wind tiles. The FP8 version of the same model lost one hidden test in Instruct mode, two equal faces, and passed every hidden test in Thinking mode. So FP8 was one test better in each mode, which is within the spread of single runs.
Qwen 3.6 35B in NVFP4
Qwen 3.6 35B passed 11 of the 12 hidden tests in Thinking mode, but built no working game in Instruct mode. In Thinking mode, the model needed only six answers and one check (see "One run step by step"). Its only mistake: U with an empty history did not clear the selection.
In Instruct mode, the first version of the file had two compile errors: a text joined with a number by +, which SC# does not allow. The model then answered three times with the whole file pasted into its answer instead of a tool call that changes the file. The run stopped after three answers without a tool call, and the file still did not compile, so all hidden tests failed.
Qwen 3.8 27B in NVFP4
Qwen 3.8 27B passed 11 of the 12 hidden tests in Think: medium and 9 in Instruct mode. In Think: medium, the only mistake was in the faces: from a certain number on, all character tiles had the same picture.
In Instruct mode, the model stopped six times before it submitted, and each time it got a reminder to go on. Its game had the same kind of face problem, and one more mistake: a new game added 72 new entries to the list of removed tiles instead of starting it again (see "A new game keeps the old tiles").
How the models work
The charts in this section show what each model did on the way to its game. Fewer steps are not better by themselves: what counts is the result of the hidden tests.
Own tests
Qwen 3.6 27B in Thinking mode wrote the most tests, but no setup tested how the faces look. The tests of the models checked the layout, the free rule, removing a pair and the undo. The pictures of the faces were never compared, so the most common mistake passed every own test. Qwen 3.6 35B in Instruct mode never ran a check, so its tests never ran.
Checks and edits
Qwen 3.6 27B in Thinking mode made the most edits, and Qwen 3.6 27B in Instruct mode ran the most checks. A check compiles the game and runs the model's tests. An edit changes some lines of the file. Qwen 3.6 35B in Thinking mode wrote almost the whole game at once and needed only one check and three edits.
Unwanted tool calls
Qwen 3.8 27B in Instruct mode answered six times without a tool call, and Qwen 3.6 35B in Instruct mode three times, after which its run stopped. An answer without a tool call does not change the game, and the model gets a reminder to go on. Qwen 3.8 27B in Instruct mode also asked once for a tool that does not exist and sent one malformed call. Qwen 3.6 27B in Thinking mode had three rejected calls: a malformed call, a rewrite of the whole file and a submission while the game did not compile.
Tokens
Every tool call sends the whole conversation to the model again, so runs with many tool calls read more tokens. Qwen 3.6 27B in Thinking mode read the most, with 44 tool calls. Qwen 3.6 35B in Thinking mode read about 10 times fewer tokens than Qwen 3.6 27B in Thinking mode, for the same score. Thinking setups write more tokens, because the model reasons before each step.
One run step by step
Qwen 3.6 35B in Thinking mode built the game in six answers and passed 11 of the 12 hidden tests.
- In its first answer, it wrote the whole game, 570 lines with 9 tests, in one file.
- It made two small edits before the first check.
- The check passed 7 of its 9 tests. The number of available pairs was not computed at the start of a game, and one of its own tests expected the opposite of the rule.
- It computed the pairs at the start and replaced the wrong test.
- It submitted the game, and the submission check passed all its tests.
- The hidden tests found one mistake: U with an empty history kept the selection.
How the models fail
Tiles that look the same
In four of the six setups, two tiles with different faces looked the same in the middle of the tile. The task warns that the tests read the pixels of the middle area and that text is not part of these pixels, so faces must differ in shapes or images, not only in text. The models painted the faces as small images, as part B asked, but in each game some of the images were equal. Qwen 3.8 27B in Think: medium drew the character tiles with a pattern of up to nine triangles:
The other games failed in a similar way:
- Qwen 3.6 27B, Instruct: the character tiles had the same red bars and differed only in a digit drawn as text.
- Qwen 3.6 27B, Thinking: the West and the North wind were drawn with rectangles, and the extra rectangle of the North wind lay inside the shapes it already had, so both pictures were equal.
- Qwen 3.8 27B, Instruct: the one-stick and the two-stick bamboo tiles both drew a single stick in the same place.
A new game keeps the old tiles
The game of Qwen 3.8 27B in Instruct mode doubled its list of removed tiles at every new game. The first version started the list again with removed.Clear(). Later, the model rewrote the new game so that every deal can be won, and the clearing line was lost:
Two hidden tests failed: the state of a new game, and a new game with Enter. The model's own tests did not check the size of the list after a second game.
Small rules about the selection
Two games broke a rule about the selection that the task states in one line.
- Qwen 3.6 27B, Instruct: a click on a tile that is not free shows a short sign, as part B asks, but it also cleared the selection. The task says that such a click changes nothing.
- Qwen 3.6 35B, Thinking: U clears the selection also when there is nothing to undo. The model cleared it only inside the branch that puts back a pair:
if (Input.WasPressed("U") && history.Count >= 2)
{
    ...
    selected = -1;
}
The whole file in the answer
Qwen 3.6 35B in Instruct mode lost the run because it never changed the file again. After the first version, it explained the compile error correctly: a number must be turned into text before it is joined with a text. But instead of a tool call that changes two lines, each answer contained the whole file as text, with the same error still in it. After three such answers, the run stopped, and the file did not compile. The same model built a game with 11 of 12 hidden tests in Thinking mode.
Conclusion
Five of the six setups built a playable Mahjong game, and three of them lost only one hidden test.
- Qwen 3.6 27B: a working game in both modes. Thinking mode lost one test (two equal faces), Instruct mode two (equal faces and the selection rule). FP8 lost one test in Instruct mode and none in Thinking mode.
- Qwen 3.6 35B: 11 of 12 hidden tests in Thinking mode with the fewest steps and tokens. Instruct mode built no working game, because it pasted the file instead of changing it.
- Qwen 3.8 27B: 11 of 12 hidden tests in Think: medium. Instruct mode needed six reminders and lost three tests.
For a game played with the mouse, all three models in NVFP4 can get the rules almost right in one attempt, preferably in a thinking mode. The weak point is what the models do not test: the pictures on the screen, and a new game after a game.