Battle City-like game built by Qwen 3.6 and Qwen 3.8 as agents
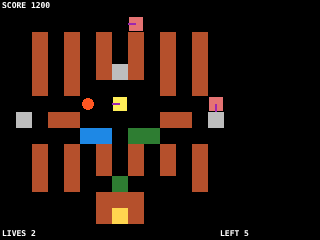
We asked Qwen 3.6 27B, Qwen 3.6 35B and Qwen 3.8 27B in NVFP4 to build a Battle City-like tank battle game in SC# as an agent: write the code and its own tests, check them, fix the problems and submit the game. 16 hidden tests checked the result. Qwen 3.8 27B in Think: medium passed every hidden test, Qwen 3.6 35B in Thinking mode and Qwen 3.6 27B in Instruct mode came close, and the run of Qwen 3.6 27B in Thinking mode was stopped by a server error and has no result.
Author: Piotr SzawdyńskiPublished: 2026-10-28
Introduction
Can a local model build a tank battle game on its own, test it and submit working code? We gave Qwen 3.6 27B, Qwen 3.6 35B and Qwen 3.8 27B the same task: write a tank battle game like Battle City as an app in SC#, our C#-like scripting language. Each model worked as an agent: it wrote the game, ran its own tests, fixed the code and submitted the game. Then 16 hidden tests checked whether the game follows the rules.
How a run works, how the task and the hidden tests are built and how we make sure the tests are fair is described in How we test local models that build apps as agents. This article covers only the results and the mistakes.
- Models: Qwen 3.6 27B; Qwen 3.6 35B, a mixture-of-experts model with about 3B active parameters; Qwen 3.8 27B, a newer version of the 27B model.
- Modes: Instruct mode and Thinking mode. Qwen 3.8 27B has thinking levels; we ran Think: medium.
- Quantization: NVFP4, a 4-bit format that needs about half the memory of FP8.
- Runtime: vLLM 0.30.0 with matching settings for all models.
Every setup ran the task once, and that run counts. We did not rerun failed runs. The aim is to show what a user can expect from one attempt, not the best possible result.
One run has no result: the run of Qwen 3.6 27B in Thinking mode was stopped by a server error before the model answered. We explain this below.
The task
The game is a tank battle on a grid of 13 x 13 cells. The player drives a tank with the arrow keys and fires with Space. Bullets destroy bricks, stop at steel and fly over water and trees. Enemy tanks appear at the top of the board, drive around and fire back. The player must protect the base at the bottom. Power-ups make bullets faster, give a shield, destroy all enemies or freeze them for a while. The player wins after 20 enemies are destroyed.
The exact rules the hidden tests check include the board as a map of characters, the order of the steps in each frame, when a new bullet starts to move, bullet speed, what a bullet does on each kind of cell, how often enemies move, appear and fire, the effects and durations of the power-ups, and the colors and positions of everything on the screen. The model chooses how to build all of this.
Results
Qwen 3.8 27B in Think: medium passed every result. Qwen 3.6 35B in Thinking mode and Qwen 3.6 27B in Instruct mode came next, Qwen 3.8 27B in Instruct mode passed 10 of 17 results, and Qwen 3.6 35B in Instruct mode built no working game. The chart below shows the score of each setup: the share of passed results, the build of the game and the 16 hidden tests. Qwen 3.6 27B in Thinking mode is not in the chart, because its run was stopped by a server error and has no result.
Qwen 3.6 27B in NVFP4
Qwen 3.6 27B built a working game in Instruct mode and passed 13 of the 16 hidden tests. Its run in Thinking mode has no result. In Instruct mode, the game moved a new bullet in the frame it was fired, which broke two tests, and enemies did not fire often enough (see below). The board, the movement, the bullets on each kind of cell, the power-ups and the screen were correct.
In Instruct mode, the model wrote a large first version and fixed it in steps. Later it repeated one old answer again and again: 28 of its edits were refused, because they repeated changes that were already in the file. Between these answers it still made progress and submitted the game.
The run in Thinking mode was stopped by a server error before the model sent its first answer, so the model never worked on the task. We do not rerun benchmarks, so this setup has no result in this test. It is not a model failure.
Qwen 3.6 35B in NVFP4
Qwen 3.6 35B built a nearly correct game in Thinking mode, but no working game in Instruct mode. In Thinking mode, the final game passed 14 of the 16 hidden tests. One row of the board map was copied with one empty cell too few, and the tanks were drawn one cell up and left of their place (see below). The model never submitted the game: it worked until the run reached its step limit, and the last version of the file was graded.
In Instruct mode, the first version of the game did not compile because of one line, and the model never fixed it. It found the cause in its text, but stopped calling tools (see below).
Qwen 3.8 27B in NVFP4
Qwen 3.8 27B passed every hidden test in Think: medium, but only 10 of the 16 hidden tests in Instruct mode. In Think: medium, the model built the game in steps, checked the timing rules with its own tests before it submitted the game (see "One run step by step").
In Instruct mode, the model built the game logic, but it moved a new bullet in the frame it was fired and counted the timers down at the wrong point of the frame. It also never drew the trees, the power-ups and the bullets. Before it could finish, one of its answers ran into a loop and the run ended (see below).
Qwen 3.8 27B in Think: medium was the only setup that passed every hidden test. Qwen 3.6 35B in Thinking mode and Qwen 3.6 27B in Instruct mode came close. With one run each, this is a hint, not a proof.
How the models work
The charts in this section show what each model did on the way to its game. Fewer steps are not better by themselves: what counts is the result of the hidden tests. Qwen 3.6 27B in Thinking mode is not in these charts: its run stopped before the model did anything.
Own tests
The number of tests the models wrote did not predict the result. Qwen 3.6 27B in Instruct mode wrote 11 tests, and Qwen 3.8 27B in Think: medium wrote 12. Both models wrote a test for firing, but only Qwen 3.8 27B checked where the bullet is right after it is fired. Qwen 3.8 27B in Instruct mode wrote only two tests, both for the start of the game. Qwen 3.6 35B in Instruct mode is not in the chart: its game never compiled.
Checks and edits
Qwen 3.6 35B in Thinking mode needed the most checks and edits. A check compiles the game and runs the model's tests. An edit changes some lines of the file. Qwen 3.6 35B in Thinking mode fought compile errors for most of its run: 14 of its 18 checks reported a compile error. Qwen 3.8 27B in Think: medium needed 6 checks and 10 edits for a game that passed every test.
Unwanted tool calls
Qwen 3.6 27B in Instruct mode spent 28 tool calls on refused repeated edits, and Qwen 3.8 27B in Instruct mode had 15 other rejected calls. Qwen 3.6 27B sent the same old answer with the same edit many times; each time the edit was refused, because the file already contained it. Most rejected calls of Qwen 3.8 27B referred to text that the answer did not contain, and some had broken call syntax. Qwen 3.6 35B in Thinking mode had two calls with broken call syntax, one rejected attempt to write the whole file again and one rejected submission: it tried to submit the game while one of its own tests failed. Qwen 3.6 35B in Instruct mode had two rejected edits. Qwen 3.8 27B in Think: medium had two rejected calls, which it sent again correctly.
Tokens
Every tool call sends the whole conversation to the model again, so runs with many tool calls read far more tokens. Qwen 3.6 35B in Thinking mode read about four million tokens, most of them because of its long fight with compile errors. Qwen 3.6 27B in Instruct mode read three and a half million tokens, largely because of the 28 repeated answers. Thinking mode writes more tokens because the model reasons before each step.
One run step by step
Qwen 3.8 27B in Think: medium built the game in small steps and tested the timing rules before it submitted the game.
- It started with a skeleton: the variables, the board and two tests.
- The first check found an array declaration, which SC# does not allow. It used a list instead.
- One of its own tests expected the base in the wrong column. It needed three tries to count the row correctly.
- It added movement and firing, then the bullets, the enemies, the spawning and the power-ups. In the same step, it made sure that a new bullet does not move in the frame it is fired.
- It fixed a stray brace and a missing line. One edit referred to text that the answer did not contain, and one call had broken call syntax; it sent both again correctly.
- A check showed 8 of 12 own tests passing. All four failures were wrong expectations in its own tests: how many frames a bullet needs to reach the next cell, and that the shield and the timer already go down in the frame they start. The game followed the task, so the model fixed only the tests.
- All 12 of its tests passed. It submitted the game, and all 16 hidden tests passed.
How the models fail
The new bullet moves too early
Qwen 3.6 27B and Qwen 3.8 27B in Instruct mode both moved a new bullet in the frame it was fired. The task says that a new bullet starts at the center of the tank's cell and does not move in this frame. Only a bullet that existed before the frame moves. Both games create the bullet and then move every active bullet in the same frame:
This broke two hidden tests in each game: the bullet position after firing, and the faster bullet with a star power-up. Qwen 3.6 27B even wrote in a comment of its own test that the bullet "fires this frame but doesn't move". But the test checked the bullet only after 30 more frames, so it passed with the wrong code.
Timers count down at the wrong point
The game of Qwen 3.8 27B in Instruct mode counts the timers down at the start of the frame instead of at the end. The task lists nine steps for each frame, and the move cooldown, the shield and the freeze timer go down in the last step. So a shield that starts in a frame shows 299 at the end of that frame, not 300:
Three hidden tests failed because of this: the shield after the player is hit, the helmet and the timer power-up. Two more failed because of the early bullet move. The sixth failure was on the screen: the game never drew the trees, and also no power-ups and no bullets. The model wrote only two tests, both for the start of the game, so none of these mistakes showed up in its own checks.
Enemies fire too rarely
In the game of Qwen 3.6 27B in Instruct mode, enemies could go more than 120 frames without firing. The task says that while enemies are on the board, a new enemy bullet appears at least once every 120 frames. The model counted frames for this rule, but only inside the enemy step, which runs every 8th frame:
if (frameCounter % 8 == 0)   // the enemy step
{
    // ... enemy movement ...
    shootTimer++;
    if (shootTimer >= 120)   // reached only after 120 enemy steps
    {
        shootTimer = 0;
        FireEnemyBullet();
    }
    if (RandomInt(0, 60) == 0 && ebX.Count < 4) { FireEnemyBullet(); }
}
The counter reaches 120 only after 960 frames. Random shots filled some gaps, but not all of them: the hidden test found a gap of 120 frames without a new enemy bullet.
A map row and tanks off their cells
Qwen 3.6 35B in Thinking mode passed 14 of the 16 hidden tests, but made two copying mistakes. In row 6 of the board, it put four empty cells in the middle instead of five, so two bricks and one steel block moved one cell to the left:
The second mistake was in drawing. The task says that cell (x, y) starts at pixel (16 + x * 16, 16 + y * 16), because the board has a 16-pixel border. The model's tank and gun barrel used x * 16 without the border, so they were drawn one cell up and left of their place. At the start of a game, the gun barrel of the player's tank then covered 16 pixels of a brick, and the hidden test that counts the brick pixels on the screen failed. We rebuilt the drawing code from the log: it gives exactly the same pixel count as the hidden test.
One compile error and a loop
Qwen 3.6 35B in Instruct mode and Qwen 3.8 27B in Instruct mode lost their runs in two different ways.
- Qwen 3.6 35B, Instruct: the first version declared several variables in one line, for example
int playerX = 4, playerY = 12, playerDir = 0;. SC# does not allow this, and the game did not compile. The model tried two edits that were rejected and one that did not touch this line. Then it answered three times with text only. In one of these answers it named the cause correctly, but in its last answer it said that such declarations are allowed. The game never compiled. - Qwen 3.8 27B, Instruct: in one answer, right after a call to check the game, the model kept writing invented closing tags, one after another, until the runtime stopped the answer as broken output. The run ended there, and the last version of the file was graded: a game with correct logic in most places, but without trees, power-ups and bullets on the screen.
A server error
The run of Qwen 3.6 27B in Thinking mode was stopped by a server error before the model answered. The request to the model server failed, so the model never received the task and never wrote any code. We do not rerun benchmarks, so this setup has no result in this test. This says nothing about how Qwen 3.6 27B in Thinking mode builds this game.
Conclusion
Qwen 3.8 27B in Think: medium passed every result. Qwen 3.6 35B in Thinking mode and Qwen 3.6 27B in Instruct mode came close, and Qwen 3.6 27B in Thinking mode has no result.
- Qwen 3.6 27B: 13 of 16 hidden tests in Instruct mode; the new bullet moved too early and enemies fired too rarely. The run in Thinking mode was stopped by a server error before the model answered, so there is no result for that setup.
- Qwen 3.6 35B: 14 of 16 hidden tests in Thinking mode, with a wrong map row and tanks drawn off their cells. In Instruct mode, one compile error was never fixed.
- Qwen 3.8 27B: all hidden tests in Think: medium. In Instruct mode, wrong timing in the frame and unfinished drawing cost 6 of 16 hidden tests.
For a game with many timing rules like this one, Qwen 3.8 27B in Think: medium in NVFP4 was the safest choice in this test. In Instruct mode, check that the rules about the first frame and the order of the steps are tested.